Failure standards

This week, Ofcom published the first of doubtless many reports on the impact of the Online Safety Act, which came into force in 2025. In the report, Ofcom acknowledges that there has been little change in the amount of “harmful material” children encounter online. The one bit of success appears to be that children are less able to access mainstream pornography sites because of age verification – but children still see pornography via social media, messaging, and gaming services. Ofcom wants to add body stigma and depression content to the list of types of “priority content” deemed harmful to children.

This is all without the proposed social media ban, which, separately, Ofcom warns may bar 100,000 16-to-17-year-olds because they have neither a passport nor a driver’s license to act as backup when other methods of age verification fail.

As Mike Masnick puts it at Techdirt, the OSA is ineffective, so Ofcom concludes we need more of it. So very Yes, Minister – specifically the episode The Challenge, in which a local government administrator proposes that every policy should be accompanied by criteria by which it could be declared a failure – “failure standards”. The civil service is horrified.

To mark Andy Burnham’s June arrival as prime minister, the Open Rights Group proposed a reset of digital policy. ORG advocates giving users better tools, publishing government content more widely so users aren’t forced to use Facebook and X, and shift government advertising budgets to local news sites. These all seem sensible.

In a new analysis of age-gating in Australia from DefendDigitalMe, Jen Persson and Madeleine Stone warn against conflating the process of age verification and the desired outcome of making children safe online. “Age checks on their own leave the harms children face online largely untouched, while building a permanent identity layer, often tied to a live face scan, between every person and the digital public sphere. The cost and risk of that layer fall first on the children these policies are said to protect.” They conclude that there are better alternatives: create protections for all users, not just children; subject new high-risk features to human rights assessments; enforce existing law; act on specific harms; and improve digital literacy. And: build in off-ramps so that policies don’t work can be ended. (RIP Humphrey Appleby.)

“The harm lies in platform design and engagement-driven business models,” they write, citing the Council of Europe’s human rights commissioner, “not in children’s access.”

***

It is a truth universally acknowledged that stories about absurd new uses of AI must invoke Philip K. Dick. And so that is how Bloomberg Law announces that the state of Delaware, the first choice of American corporations, plans to create a new form of company – autonomous, bot-run Artificial Intelligence Companies, which would be allowed to claim limited liability for owners and full corporate “personhood”, sign contracts, make business decisions, own assets, and bring lawsuits. The PKD will be in the as-yet-unreleased details. The proposal would enable a 30-month test in a “regulatory sandbox”, possibly beginning next year. Argentina has similar plans. Professor Yonathan Arbel suggests the appropriate response is “terrified excitement”.

Maybe, if you’re a lawyer. My own response is more like exasperation. Those cited in the Bloomberg piece claim that legal penalties will “guide” AICs to behave “responsibly” by consuming resources that their programming would identify as needed for business expansion. What fantasy thinking is this? If recent events have taught us anything, it’s that AIs will find the shortest path to their assignment, even if that means using strategies humans would reject as illegal or ethically wrong. Does anyone really think AIs will be less inclined to create cover-ups than human-run Volkswagen, Enron, Theranos, or Bernie Madoff? Given the history of human interactions to learn from, AICs will sue human beings who try to expose their wrongdoing rather than decide to behave correctly. Dishonest humans will love them.

Granted, human-run companies are no more scrutable at the moment; many are thickets of chatbots. But at least human CEOs fear prison and poverty; AIs fundamentally can’t care about either.

As on their 2009-2016 show The Good Wife, TV writers Michelle and Robert are ahead of the headlines. In the third episode of their new series, Cupertino, “Juno”, an AI incorporates in order to gain standing to file a lawsuit.

The good news, according to Joe Miller and Sujeet Indap at the Financial Times, is that at least some people are paying attention. The chair of the House Oversight committee, James Comer (R-KY), has already written to Democratic Delaware governor Matt Meyer asking for more detail, concerned that “Delaware’s AIC proposal could be used to protect powerful AI companies and their investors from responsibility for reckless harmful actions”.

At Ars Technica, Jon Brodkin traces the idea to a July 2026 op-ed in Fortune by John Nay and secretary of state of Delaware Charuni Patibanda-Sanchez laid out their case for AICs. In their argument, wrapping AICs in a legal structure is essential because prohibiting autonomous software from transacting will be impossible. IANAL, but surely the humans in charge of the company the autonomous software represents are liable *now*. What’s the problem?

Illustrations: Local Halloween decoration in 2026.

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.
Time thieves

Two things you can never get back: time and teeth.

The proliferation of refund fraud means that before sending you a refund, the US Internal Revenue Service requires you to verify your tax return. The IRS letter directs you online – first to verify your identity via a third party commercial company called id.me and *then* to verify the return at the IRS site. I had to do the personal part of this via video call. This meant first typing in a load of details I wouldn’t normally disclose on a first date, then a 20-minute wait until an obviously bored human avatar got on the call and had me hold up the various documents. Only then could I proceed to the IRS site to answer questions like “what number appears on line 31a?”

Shadow work, to be sure. Like others, I’m worried about the potential consequences of being a data hostage to this unknown company at government behest. But first…we talk very little about the hours we all spend doing stuff like this because so many trust mechanisms are broken. A recent essay – which I cannot now find – complained about “time thieves”. A recent essay that I *can* find, The Last Quiet Thing, talked about the labor imposed on us by modern devices that require constant tending – smart watches, for example. The same author, Terry Godier, has followed up more recently with Phantom Obligation, which highlights interface design choices intended to make us feel guilty if we’re not keeping up – with social media and RSS feeds, emails, and so on. Godbier traces the beginning of this to answering machines, whose blinking lights imposed an obligation that previously did not exist. “Phantom” obligations, because in the case of social media and RSS, no one is really waiting for your response.

Ignoring all that is easy stuff for someone who discovered her ability to let a phone ring without answering in 1972, even before answering machines. Much less ignorable, however, is the web’s constantly-growing thicket of anti-robot tests: captchas, verification tests (which my instance of Firefox routinely sends into an infinite loop), and so on. In 2018, the comedian John Mulaney noted how much of the day we spend proving to robots that we are *not* robots – and it’s gotten so much worse since then. This is a part of the price of fraud that is rarely considered: the amount of time we all spend as unpaid guardians of other people’s security.

***

Most of the time, anyone campaigning for anything has to work really hard to prove their case. When it comes to issues of technological dependence, however, the technology companies are doing the job themselves, whatever their own interests.

This week, a power outage took down a Google data center with cascading effects to banks HSBC, Revolut, and Lloyds, as well as government sites and Royal Mail. As Aisha Down points out at the Guardian, last year’s Amazon outage was bigger and had more widespread effects. In that same month, Cloudflare went down and a DNS error in Microsoft Azure caused another widespread outage. As a way of showing dependence on individual companies, these developments were highly effective.

But we are dependent on technologies as well as companies, and the application layer of the Internet seems increasingly fragile. This week, two decade-old critical flaws were found in PHP, a scripting language used for 70% of websites whose language is known, including publishing sites run on Drupal. Joomla, and WordPress, Slack, some parts of Wikipedia, Steam, and many government websites. Also: 4Chan.

The fallout will continue as AI accelerates attacks on the many so-far-unpatched websites. We are in a new era, where AI models find flaws that other AIs can exploit more effectively than humans ever could. Time to ensure there are backup methods of getting things done. Moscow is already discovering the dangers of overdependence on digitization..

***

At the Washington Post, Megan McArdle surmises that novelists may soon have to pass their new manuscripts through AI detectors before publication. In pondering this, she speculates that someone who’s willing to read chatbot-generated fiction might eliminate the middleman (that is, the writer) and subscribe directly to the chatbot. For someone who reads the most formulaic of genre fiction, maybe: no waiting around for your favorite author to produce the next installment.

What strikes me, though, as in the two cases of canceled publicationsthis summer, plus the latest accusations against a prize-winning story, is that the experts who choose gems from dross and are tasked to identify subtleties of excellence are picking AI-generated stories and novels. What does that tell us about their supposed super-sophistication? And: what does it say that all three of this year’s high-profile AI-cancellation cases involved non-white writers?

McArdle herself seems inclined to wholly trust the AI detection software Pangram, which touts a peer-reviewed paper that awards it high marks for accuracy. However, the study is specifically focused on higher education – academic writing, not popular or literary fiction, which has less consistency of form and style. It would be good to see a properly conducted wider study before assuming that it’s good enough to destroy careers.

Illustrations: Sign of sentient life inside the post office.

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.
Escaping the sandbox

This week, France became the first European country to pass a social media ban. Under-15s will be blocked from opening new accounts on social media from September, and banned entirely from January 2027. As the BBC notes, implementation will require everyone in France to prove they are over 15 to use social media. Other European countries may follow.

At the New York Times, Mark Landler reports that similar laws are in progress in Canada, Italy, Poland, Portugal, and Spain. The EU is considering a bloc-wide law. The UK announced a ban to begin in 2027 last month and published a fact sheet last week – unless new prime minister Andy Burnham changes tack, as he has by canceling digital IDs.

At Le Monde, Florian Reynaud traces the origins of this whole idea of social media bans to a 2019 article in The Atlantic by Conor Friedersdorf. In it, Friedersdorf proposed not only a ban on social media sites for kids but a separate kid-friendly “Internet” with services designed just for them (this part was actually not a new idea).

A fundamental problem, no matter what restrictions or sandboxes you want to create, is that social media bans require sites to determine who’s allowed in and who isn’t. So, no social media ban without age verification, which the UK had already introduced.

Worth noting: at the Guardian, Amelia Gentleman interviews Candice Odgers, who has concluded from *talking to kids* that social media bans will make teens’ problems worse, not better. At The Conversation, Andy Phippen, who also listens to children as well as parents, is equally dubious.

Because Australia was first, everyone looks at its results. The BBC reported in April, four months after Australia’s social media ban began, that 61% of 12 to 15-year-olds still had access to one or more accounts and that a little over half of those who had used social media before the ban believed the ban was making no difference to their online safety. In July, researchers found their consumption of news had dropped. The Independent offered uncertainty. A few weeks ago, at the Guardian Anna Bawden reported that a newer study from the University of Newcastle published in the British Medical Journal finds that 85% of Australian 12 to 17-year-olds are still using social media, more than half of them through their own accounts.

Numbers are easier to assess than emotional states, which means that whether the bans “work” is more easily and immediately measured by how many kids evade the ban – and this in turn means next steps will inevitably be aimed at shrinking that number without waiting the years necessary to assess the real results.

France is already on it, aiming to restrict VPNs, as Skye Jacobs reports at Techspot. At Techdirt, Mike Masnick warns that Australia is, too. And so is the EU, to prevent kids from bypassing its easily hacked age verification app.

For now, the UK is holding out. Last week, the UK’s then-minister for online safety, Kanishka Narayan, told BBC Breakfast News that the government has decided against banning VPNs since they have many privacy and security uses. This was later confirmed in writing by then-technology secretary Liz Kendall. In the week since, Kendall’s department has been abolished, and Narayan has been made the UK’s first minister for artificial intelligence. So we’ll see if at least that amount of sense continues to prevail.

***

Much excitement this week when OpenAI announced that in a cybersecurity test an unreleased model broke out of its sandbox and mounted a cyber attack on Hugging Face, a community for sharing machine learning models and datasets. At his blog, Simon Willison analyzes what happened in more detail.

If you’ve read Janelle Shane’s book, You Look Like a Thing and I Love You, Willison’s explanation makes perfect sense. Shane documents many cases in which AI software, given a task, takes “shortcuts”. Because computers and software are literal (paperclip maximizers, these shortcuts are sometimes surprising to humans. Here, OpenAI removed the guardrails, locked the model in a sandbox, and told it to solve a bunch of benchmark problems. The model “cheated” – that is, instead of working directly on the problems, it found a vulnerability in the sandbox that let it access the public Internet, and attacked Hugging Face as a likely source of the problems’ solutions. If it were a new-model car kept in a locked parking lot that turned itself on, crashed through the barriers, and drove into a house across the street, it wouldn’t seem so mystical; we’d expect the company to revamp the car’s electrical system, strengthen the barriers, and pay for the damage.

Willison goes on to argue that a key issue is asymmetry of knowledge – that is, that the guardrails that protect us from “our” AI software don’t apply elsewhere, so blocks on Chinese AIs prevent us for finding the vulnerabilities in our own software and services that they can. At last, a sensible reason for caring if another country is “winning the AI race” (whatever that really means).

Illustrations: Children swimming in the summer, by Japanese artist Ando Hiroshige, 1797-1858 (via Smithsonian collection.

Also this week: The Plutopia podcast talks with Rob van Eijk on digital sovereignty, AI, and privacy in the EU.

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.
International relations

The US Supreme Court’s decision this week in Trump v. Slaughter, giving the US president the power to control supposed-to-be independent agencies set up and funded by Congress, may be as profound internationally as it is domestically. In his newsletter, the economist Paul Krugman calls the president’s new power “dictatorial”, and notes the Court’s exception for the Federal Reserve. Krugman highlights the importance to average citizens of the Federal Trade Commission, which oversees consumer protection and the US’s meager privacy law. It is one of the agencies Trump now fully controls.

At day later, at Euractiv, Claudie Moreau reported that as a direct result Max Schrems and his NGO, noyb, is preparing a legal challenge to the three-year-old EU-US Data Privacy Framework.

Quick recap. This is the third time Schrems, an Austrian citizen, is challenging a formal legal arrangement for permitting data flows from the EU to the US. The saga began in 1998, when the EU Data Protection Directive, passed in 1995, came into force. To enable data flows to the US, the EU and US negotiated the Safe Harbour agreement. Then came Edward Snowden’s 2013 revelations of US intelligence spying. A bunch of lawyering later, in 2015, the European Court of Justice struck down Safe Harbour. In 2016, the EU and US replaced it with Privacy Shield, based on the US passage of the 2015 Judicial Redress Act, which granted non-US citizens limited rights to access redress in US courts for illegal data transfers.

Days after arriving in office in 2017, Trump issued an executive order demanding that agencies ensure that their privacy policies exclude those who are not US citizens. In a flurry at the in-progress Computers, Privacy, and Data Protection, many asked, had he just killed Privacy Shield? Schrems’ second case was already underway, and in 2020 he won again, when the European Court of Justice struck down Privacy Shield.

“There must be no Schrems III,” the Dutch MEP Sophie int’ Veld said a few months later. That possibility pervaded CPDP 2022. Yet all agreed the big issue was and is lack of enforcement.

The 2023 adoption of the Framework was enabled by the US creation of the Privacy and Civil Liberties Oversight Board to handle complaints from and redress for foreigners whose privacy rights have been violated. Last year, again days after taking office, Trump gutted the PCLOB. Many wondered then if the Framework could survive. Schrems commented, “This deal was always built on sand.”

The SCOTUS ruling this week granting US presidents free rein to control independent agencies like the FTC, noyb writes in a press release / blog posting, “…the entire structure of the EU-US Data Privacy Framework has just collapsed”. It also notes that EU treaty law requires such agencies to be independent – and counts 259 times that the EU relies on the FTC in its data flow decision.

“Even in the European Commission’s logic, the basis for any EU-US data transfer deal is dead,” Schrems concludes. Because the Framework must be actively repealed or ruled illegal by the courts, noyb is both filing a lawsuit and asking the European Commission to repeal it.

And so begins Schrems III.

***

This week I presented the talk I did at Greenwich Skeptics in April for the Cambridge Skeptics. Titled “What We Talk About When We Talk About AI”, the talk was an attempt to disentangle the different things people mean when they say “artificial intelligence”. The AI we have – generative AI, image generators, scoring systems, surveillance systems – has little in common with the original idea mooted by Alan Turing in 1950 or the problems the Dartmouth workshop sought to solve over the summer of 1956.

The founders and CEOs of AI companies, however, seem quite happy for us to conflate the two, since it makes them sound more worth investing in. Demis Hassabis, for example, founded Deep Mind (since 2014, part of Google) with the mission statement, “Solve intelligence. Then use that to solve everything else.” With respect to at leaast some intractable problems this is obviously nonsense. We have long known what needs to be done about climate change. All the intelligence in the universe will not create the political will to do the things we already know need to be done.

Many of the things we want from AI – automation, helpers, guardians, (sadly) weapons, companions – are things humans have wanted as long as there have been humans and have many precursors. Some of these constructs, both fictional (Asimov’s Laws, Rosey the Robot), and non-fictional (Arthur C. Clarke’s Laws of Science) come up routinely in academic and legal conferences to this day. I personally don’t believe today’s “AI” paradigm will lead to a superintelligence or a new form of consciousness (as net.wars readers probably already know). But the evidence is clear that today’s “AI” can do plenty of damage to today’s people and places.

The talk ended with a few thoughts about how to respond: resist the inevitability narrative; change the framing; be specific about naming systems, their purposes and owners; and count the opportunity costs.

The talk was not recorded and is not online, but the references are.

Illustrations: Max Schrems, in 2024 (via Murielle Gerber and EPFL media library at Wikimedia.

Also this week: At Plutopia, we talk to computer security professor Steve Bellovin about his newly-released free book on home security Don’t Get Hacked!.

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.
The sovereignty paradox

The year since the 2025 Computers, Privacy, and Data Protection has made Europe more distinct as an entity. Two years ago, we were being chastised for paying insufficient attention to structural corporate power. At this conference last year, we were warned about “simplification”, since published as the Digital Omnibus that threatens to undo some aspects of data protection and other privacy rights.

This year, we heard a lot about “European values”. Invoked as a metric: does “simplification” measure up or is it a sign of weakening? Invoked as a frame to guide developing the digital euro. Invoked as a reason why digital sovereignty is increasingly essential. In November 2025, 23 European countries signed a declaration embracing the latter as a policy.

And yet, although Plixavra Vogiatzoglou introduced a panel discussion by calling digital sovereignty “urgent because of Trump’s trade wars”, she then said it was unrealistic.

There’s a lot to like in the 2025 declaration, which lists as principles open source solutions, the principle of common assets, competitive markets, and democracy. The problem, as Vogiatzoglou said, is that Europe doesn’t make all the necessary components for building its own bottom-to-top stack. The investment required is likely to favor the wealthiest countries, deepening the imbalances that already favor US technology companies.

This is the “sovereignty paradox,” as Zuzanna Warso called it. Replicating the current infrastructure with little change other than a different owner isn’t the right goal – as someone said later, who wants a European Palantir? Warso favors redesigning the technical ecosystem to foster the “digital commons” – and being honest about the tradeoffs.

The same theme reappeared in a discussion of agentic assistants: they will ultimately sit on infrastructure belonging to the same few hyperscalers. Frederika Kaltheuner posited three scenarios: full vertical integration (like Google), integrated models and software (Anthropic and Claude Code), or open source and smaller models, which she thought was Europe’s only opportunity for sovereignty.

All of this seems set to get worse with agentic AI, which, Apple’s Gary Davis said, will allow agents onto all our devices capable of listening, observing, inferring, and acting across apps. What controls do we want? I personally want the control of barring this proposed technological future from my life, but how many of us will have that choice? Davis also noted the European Commission’s release, a few weeks ago, of proposals for requiring Google to allow competing AI services onto Android. If they follow through, he said, it will allow a large-scale privacy and security experiment on European users. While Davis’s employer has its own rasons for opposing this, he has a point. This is untried technology controlled by a handful of companies that could give them overwhelming power over individuals.

Among other new threats to privacy was eye tracking, a constant reality in games played with virtual reality headsets that could easily spread more widely via augmented reality smartglasses. The only way for Europe to counter this, Michael Raschke said, is to create large market-leading companies to act as gatekeepers to intermediate to meet European expectations of security and privacy.

A discussion of the digital euro had this same backdrop: part of the point is to reclaim some of the payments business from US giants Visa and Mastercard. Although, that’s over-simplified: the plans include offline and online versions of the digital euro which do different things. The offline version is meant as a digital reinterpretation of cash that allows anonymous person-to-person payments. The online version is…well, it’s hard to distinguish it from a bank transfer, except that “central bank digital currency” makes stuffy old banks sound kind of cool? Or it did when “crypto” was new and hot. The British equivalent, the digital pound, is in the design phase.

Those thoughts made Leon Schumacher‘s spirited intervention satisfying: where, he asked, was future-proofing against quantum computing, or accommodation for agentic AI, which is expected to underpin…well, no one knows quite how much in transactions, but they’re willing to guess. A trillion dollars, says McKinsey; up to $17.5 trillion, thinks Deloitte, $190 to $385 billion, per Morgan Stanley. Weirdly they all agree on *when*: by 2030. The digital euro is intended to arrive in 2029.

Meanwhile, there is simplification, which has few fans in the privacy world. As Orla Lynskey noted, simplification doesn’t *have* to mean deregulation – however, the European Commission’s proposals reduce rights, facilitate more data processing and *don’t* simplify. Plus, she added, changes of this magnitude require more time for thought and care.

Even business folk present, such as Spanish company founder Alicia Asín Pérez, thought deregulation was less important than many other constraints on business on her list. “My concern is, who area we deregulating for? What will be the consequences?” she said.

What most people favored instead is less fragmentation, and enforcement of the laws we have, a long-running theme at this event.

The former MEP Sophie in t’ Veld had a different take on European values. “We are obsessed with the US,” she said. “But it’s happening right here.” She called out government leaders for ignoring orders from the European Court of Justice, courts for rubber-stamping requests to target journalists with spyware, and called governments not using spyware complicit by their silence.

Illustrations: EU flag (via Wikimedia).

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.

First, do no harm

In the midst of the recent Labour leadership turbulence, on Wednesday May 13 Wes Streeting, who would resign from his position as the UK’s health minister a day later, published the Health bill. Among its provisions are the latest in a long line of attempts to centralize and exploit the data collected by the National Health Service. medConfidental provides a useful summary.

Two main aims have kept reappearing over the years. One is to make the health service more efficient and streamline patient interactions. Probably everyone supports this – until they read the details. Even before the bill was published, media reported the government plans to give each of us a single patient record. In the announcement, Streeting talks about the frustration of having to repeat your medical history to every new physician. True; on the other hand, rehashing the medical history is an opportunity to correct errors and misperceptions. This is where patients need choice and control.

The second recurring theme is using patient data to fuel research. Most people support that, too, as long as the data isn’t handed off to commercial companies to exploit for profit. Antecedents here include 2014’s care.data and a its revival in 2021. On his web page, the late Ross Anderson, who extensively researched the security of clinical information systems, documented examples going back to the mid-1990s.

The key complaint about single patient records is the rupture of the individual trust relationship between individuals and their doctors’ surgeries. Traditionally, the GP is the gatekeeper to the rest of the health service. GPs refer you to specialist consultants, provide continuity, and keep your notes. The single care record turns all this into a centralized database under the control of the health minister with many downsides that may not be immediately apparent, particularly to administrators focused on efficiency rather than patient care. Like Facebook, it can be impossible to wholly opt out even if you don’t use the service because others’ records may carve out your shadow.

In March, the worst happened to show the risks: Hannah Devlin and Tom Burgis reported at the Guardian that the data held by UK Biobank turned up for sale on the Chinese site Alibaba. Since its founding in 2003, Biobank has collected detailed longitudinal health records from more than 500,000 volunteers for the purpose of research. The issue seems to have been code and data researchers stored in repositories such as Github, sharing that is often now required by funders. The data was quickly removed, but uncertainty remains.

Even before that, medConfidential warned that pandemic hospital data the government gave to Biobank could be reidentified, and posed risks to health privacy generally. In addition, medConfidential warns that Biobank’s failure to protect its data is systemic and cultural. No one denies Biobank’s value; but the security failure is a betrayal of its volunteers.

The Biobank leaks, coupled with Anthropic’s announcment of Mythos, seem to have led directly to the NHS’s announcement at the beginning of May that it is closing its open source repositories on the grounds that they expose the service to the threat of AI hacking, as former civil servant Terence Eden reports. In a second posting, Eden deplores the decision and points to significant dissent from the Government Digital Service, which explains what the NHS should do instead.

A centralized database gives the health minister great power over our most sensitive data. Naturally, all concerned promise our health information will be protected. But as medConfidential likes to remind, any promise one government makes a later government can break.

“Beware what systems you put in place,” medConfidential coordinator Sam Smith says, “because you don’t know who will be operating them.”

Always simmering in the background is the nationwide opposition to privatizing the NHS. The American medical system’s bankruptcies are warning enough.

All of these issues are heightened by the involvement of Palantir. This began during the covid pandemic, when the company offered the NHS a free puppy to gain a foothold. As Robert Booth reports at the Guardian, the company’s services have since become both increasingly expensive and increasingly controversial as Palantir’s role in military conflict and anti-immigrant actions has become better known. In February, Booth reported that health officials were warning Streeting that the public’s perception of Palantir would impede rollout and that consequently the NHS would not get value for money from the contract. There is also the tetchy matter of US law, which allows the government to demand access to data held by the international subsidiaries of US companies. Last week, Lindsay Clark reported at The Register that Palantir staff have access to patient data belonging to NHS England.

*Then* add AI. It’s not clear anyone would welcome it into their relationship with their doctors. In warning of the downsides of centralization, medConfidential puts together centralized data and AI and a long-term trend toward disempowering GPs through centralization such as apps, centralized appointment booking, and…do you want your doctor replaced by a chatbot?

Computer systems take on the values of their owners. In April, Palantir co-founder Alex Karp posted on X a 22-point manifesto widely seen as expressing values incompatible with those of health care: “First, do no harm.”

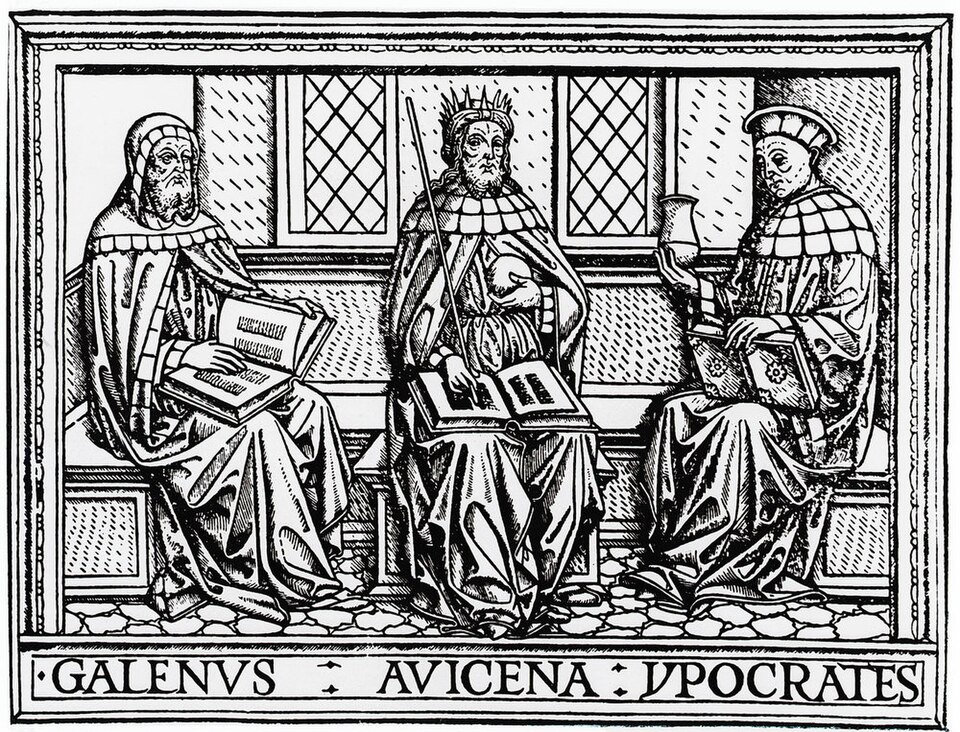
Illustrations: The medical figures Galen, Avicenna, and Hippocrates, as pictured in a 16th century medical book (via Wikimedia).

Also this week: At the Plutopia podcast, we talk to departing EFF director Cindy Cohn about her book on her 30 years of defending privacy.

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.

Power games

UK prime minister Keir Starmer’s desire to bring in a UK digital ID is awake again with the announcement that the government plans to make the IDs available for “a handful of uses” before the next general election, due by 2029, . The requisite consultation closes May 5.

At Computer Weekly, Lis Evanstad adds a summary and detail about the consultation. Government by app! What could possibly go wrong?

Among other new information in the consultation: the age for being able to get a digital ID could drop below 18, perhaps even to issuance at birth. There might be a single unique identifier to enable linking data throughout government systems. Darren Jones, the prime minister’s chief secretary, talks smoother access to government services and the ability to share only the piece of data that’s needed for a specific purpose, but not about the risks of tying everything to a single identifier whose compromise can reverberate throughout your life.

In his Guardian piece, Stacey quotes Jones, who positions the digital ID as a way to improve fairness in access to government services, which he says accrue disproportionately to “pushy” people with time, patience, and energy.

This sounds good until you read Government Digital Service co-founder Tom Loosemore‘s blog, where he notes that creating that sort of stonewalling bureaucracy is often a deliberate strategy to manage demand. Loosemore argues that agentic AI will force an end to this strategy because agents will have unlimited patience and “reduce the cost to citizens of appeals, challenges, and calculations etc to near-zero”. Instead of having to manually dig through financial records, Loosemore finds in an experiment that an AI agent can scan the documents, find the information, and present only the data required to establish the citizen’s entitlement to benefits.

He believes AI agents will also bring a new level of transparency (and perhaps “pushiness”): “AI Agents will always dig out that 93 page PDF of guidance hidden.” Governments, he writes, will be forced to “clarify and tighten policies & processes, with all the painful political trade-offs therein”.

Or: will budget-protecting governments adopt their own agentic AIs to move and re-bury the stuff they don’t want applicants to find and recalibrate their requirements to make them resistant to automation? Seems just as likely, really.

While all that was going on, significant votes took place on the future of access to online content. On Tuesday, Jennifer McKiernan reports at the BBC, MPs rejected the proposed social media for under-16s, which would have been added to the Children’s Wellbeing and Schools bill. Instead, the government is continuing to collect information from the consultation it launched on March 2, which closes on May 26.

Some MPs seem to have been persuaded by the argument – mooted by, among others, the National Society for the Prevention of Cruelty to Children – that banning children from social media will simply push them to find darker, less visible unregulated online spaces with less in the way of protection or moderation. The Commons did, however, support a government proposal to give the relevant ministers greater powers to restrict or ban children’s access to social media services and chatbots, limit their use of VPNs, and change the “age of digital consent”. The Children’s Wellbeing and Schools bill now goes back to the Lords for more discussion. .

As an unelected body, in recent years the House of Lords has often been a damper on hastily-passed legislation in response to political trends, but here they’re leading. The social media ban passed there. This week, as Dev Kundaliya reports at Computing. the Lords voted on two amendments, one to the Crime and Policing bill, the other to the Children’s Wellbeing and Schools bill. At the Online Safety Act Network blog, University of Essex professor Lorna Woods explains these in detail. The first would enable the government to amend the Online Safety Act to “minimize or mitigate the risks of harm to individuals” from illegal AI-generated content. The second would give the government latitude to change the age of consent.

Woods’ main point is the extreme power being given the government here to bypass Parliament, calling the clauses Henry VIII powers – that is, giving the government the power to change or repeal an Act of Parliament without consulting Parliament. The government’s official justification is to give the government greater flexibility to adapt on the fly to new technologies and online harms. Or to bar access to stuff it doesn’t like, presumably.

The Open Rights Group agrees, calling the plan powers to restrict the entire Internet. ORG also cites a March 0 open letter from 400 scientists and calls for a moratorium on age assurance to learn more about the technological hazards and social impact and for adopting alternative measures in the meantime, such as regulating algorithmic manipulation and providing parents with support.

At DefendDigitalMe, Jen Persson points out that the books already contain laws enabling considerable digital control of children; surveillance, she writes, is being “dressed as ‘safety'”. None of this, she writes, is compatible with children’s *rights*, which don’t seem to get much of a look-in.

Illustrations: Henry VIII, as painted by Hans Holbein the Younger (via Wikimedia.

Also this week: TechGrumps 3.38, The Bettification of Everything.

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.

Bedroom eyes

We’ve long known that much of today’s “AI” is humans all the way down. This week underlines this: in an investigation, Svenska Dagbladet and Göteborgs-Posten learn that Meta’s Ray-Ban smart glasses are capturing intimate details of people’s lives and sending them to Nairobi, Kenya. There, employees at Meta subcontractor Sama label and annotate the data for use in training models. Brings a new meaning to “bedroom eyes”.

This sort of violation is easily imposed on other people without their knowledge or consent. We worry about the police using live facial recognition, but what about being captured by random people on the street? In January’s episode of the TechGrumps podcast, we called the news of Meta’s new product “Return of the Glasshole“.

Two 2018 books, Mary L. Gray and Siddharth Suri’s Ghost Work and Sarah T. Roberts’ Behind the Screen made it clear that “machine learning” and “AI” depend on poorly-paid unseen laborers. Dataveillance is a stowaway in every “smart” device. But this is a whole new level: the Kenyans report glimpses of bank cards, bedroom intimacy, even bathroom visits. The journalists were able to establish that the glasses’ AI requires a connection to Meta’s servers to answer questions, and there’s no opt out.

The UK’s Information Commissioner’s Office is investigating, and at Ars Technica Sarah Perez reports that a US lawsuit has been filed.

As the original Swedish report goes on to say, the EU has no adequacy agreement with Kenya. More disturbing is the fact that probably hundreds of people within Meta worked on this without seeing a problem.

In 1974, the Watergate-related revelation that US president Richard Nixon had recorded everything taking place in his office inspired folksinger Bill Steele to write the song The Walls Have Ears (MP3). What struck him particularly was that everyone saw it as unremarkable. “Unfortunately still current,” he commented in his 1977 liner notes. Nearly 50 years later, ditto.

***

A lot of (especially younger) people don’t remember that before 9/11 you could walk into most buildings without showing ID. Many authorities – the EU in particular – have long been unhappy with anonymity online, and one conspiratorial theory about age gating and the digital ID infrastructure being built in many places is that the goal is complete and pervasive identification. In the UK, requiring ID for all Internet access has occasionally popped up as a child safety idea, even though security experts recommend lying about birth dates and other personal data in the interests of self-protection against identity theft.

Now we have generative AI, and along comes a new paper that finds that large language models can be used to deanonymize people online at large scale by analyzing profiles and conversations. In one exercise, they matched Hacker News posts to LinkedIn profiles. In another, they linked users across subReddit communities. In a third, they split Reddit profiles to mimic the use of pseudonymous posting. Pseudonymity doesn’t offer meaningful protection (though I’m not sure how much it ever did), and preventing this type of attack is difficult. They also suggest platforms should reconsider their data access policies in line with their findings.

It’s hard to imagine most platforms will care much; users have long been expected to assess their own risk. Even smaller communities with a more concerned administration will not be in a position to know how many other services their users access, what they post there, or how it can be cross-linked. The difficulty of remaining anonymous online has been growing ever since 2000, when Latanya Sweeney showed it was possible to identify 87% of the population recorded in census data given just Zip code, date of birth, and gender. As psychics know, most people don’t really remember what they’ve said and how it can be linked and exploited by someone who’s paying attention. The paper concludes: we need a new threat model for privacy online.

***

The Internet, famously, was designed to support communications in the face of a bomb outage.

Building it required physical links – undersea cables, fiber connections, data centers, routers. For younger folks who have grown up with wifi and mobile phone connections, that physical layer may be invisible. But it matters no less than it did twenty-five years ago, when experts agreed that ten backhoes (among other things) could do more effective damage than bombs.

This week’s horrible, spreading war in the Middle East has seen the closure of the Strait of Hormuz and the Red see to commercial traffic. Indranil Ghosh reports at Rest of World that that 17 undersea cables pass through the Red Sea alone, and billions, soon trillions, of dollars in US technology investment depends on fiber optic cables running through war zones. There’s been reporting before now about the links between various Middle Eastern countries and Silicon Valley (see for example the recent book Gilded Rage, by Jacob Silverman), but until now much less about the technological interdependence put in jeopardy by the conflict. Ghosh also reports that drones have struck two Amazon Web Services data centers in UAE and one in Bahrein.

The issue is not so much direct damage to the cables as the impossibility of repairing them as long as access is closed. The Internet, designed with war in mind, is a product of peace.

Illustrations: Monument to Anonymous, by Meredith Bergmann.

Also this week: At the Plutopia podcast, we interview Kate Devlin, who studies human-AI interaction.

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.

Saving no one

In the early 2010s, after “nano” and before “AI”, 3D printing was the technology that was going to change everything. Then it seemed to go quiet except for guns.

“First we will gain control over the shape of physical things. Then we will gain new levels of control over their composition, the materials they’re made of. Finally, we will gain control over the behavior of physical things,” Hod Lipson and Melba Kurman wrote in their 2013 book, Fabricated. As far as I can tell, we’re still pretty much in the era of making physical things that could be made by traditional methods rather than weird new shapes that could *only* be produced by additive manufacturing. More than 15 years after a fellow technology conference attendee excitedly lectured me that 3D printing was going to change everything, its growth remains largely hidden from most of us.

Until this past week, when I attended an event awash in puzzle makers and discovered that it’s been a godsend to them for making not only prototypes but also small runs of copies or published designs, freeing them from having to find space and capital for the kind of quantities required by traditional production. It’s good to see a formerly hyped technology supporting clever and entertaining human invention.

Exploding egg, anyone?

***

In one of the biggest fines in its history, the UK Information Commissioner’s Office has announced it is fining Reddit £14.5 million for failing to put in place an effective age verification mechanism to block under-13s from using the site under Reddit’s stated terms of service. The story is somewhat confused by timing: the fine is under data protection law and relates to the period before the arrival of the Online Safety Act, but the OSA’s requirement for age verification brought the changes that sparked the fine. Reddit says it will appeal.

In the UK terms and conditions Reddit announced in June 2025, the company says that “by using the services, you state that…you are at least 13 years old”. But Reddit didn’t require proof, and the ICO says that many under-13s use(d) the platform.

In July, when the Online Safety Act came into effect, Reddit added an age gate of 18 for “mature” content. Unlike many other social media sites that are just giant pools of content sorted by curation or algorithm, Reddit is a large set of distinct subReddits. Each of these communities has its own rules, social norms, and, most important, human moderators. Because of this, it’s comparatively easy to mark a particular subReddit as “for adults only”. After the July change, anyone in the UK wishing to access one of those subReddits was asked to submit a selfie or an image of a government-issued ID in order to prove their age.

The ICO’s findings state that Reddit failed to protect under-13s from accessing content that placed them at risk; that it processed under-13s’ data unlawfully (because they are too young to meaningfully consent); and that a simple statement is not a sufficient age verification mechanism (which is made clear in the OSA).

A Reddit spokesperson told the Guardian: “The ICO’s insistence that we collect more private information on every UK user is counterintuitive and at odds with our strong belief in our users’ online privacy and safety.”

I take their point; I’d rather skip the “mature” content than bear the privacy risk of uploading personal data to whatever third-party company Reddit is using for age verification. Last July, I decided I would just be a child. (Although: my Reddit account dates to 2015, so they could just do the math.)

Turns out, it may have been a wise decision. Reddit, saying it didn’t want to hold users’ personal data, chose the age verification provider Persona.

Persona deserves a look. Last week, Discord announced it would begin treating all users as teens until they’d been verified, also using Persona. The result as Ashley Belanger reports at Ars Technica was a user backlash. First, because last time Discord tried this, its now-former age verification provider’s pile of 70,000 users’ age check information was hacked.

Second, because The Rage reports that a group of security researchers found a Persona front end exposed to the open Internet on a US government server. On examination, that code shows that Persona performs 269 different verification checks and scours the Internet and government sources using your selfie and facial recognition. Discord has now announced it will delay introducing age verification – and won’t be using Persona after an apparently unsatisfactory trial in the UK last year.In a blog posting, Discord says that, like Reddit, it does not want to know its users’ identification details. It is adding more verification options.

If the world had already had a set of established trustworthy companies that specialized in age verification when the OSA came into effect, then it would make sense to turn to them to provide that service. But we aren’t in that situation. Instead, although providers have been working for more than a decade to build such systems, their deployment at scale is new.

Part of keeping children – and the rest of us – safe is protecting security and privacy – and child safety campaigners’ refusal to accept this has been an issue for decades. Creating new privacy risks doesn’t keep anyone safer – including children.

Illustrations: Six-panel early 1970s cartoon strip, “What the User Wanted”.

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.

Information wants to be surveiled

It has long been the case that the person sitting next to you on an airplane may have paid a very different price for their seat than you did. For two reasons. First, airlines don’t price seats – they price itineraries. A seat from London to New York may be priced very differently depending on whether it’s one-way, one-half of a round trip, or one stage in a larger, multi-stage journey. Second, however, airlines are sophisticated about maximizing the value of your seat, responding to patterns of peak travel (Thanksgiving, August), when you buy it, and other factors. Despite their complexity, those prices are supposed to be based on published tariffs that anyone can, in theory, calculate for themselves and come up with the same answer.

In 2012, travel and data privacy expert Edward Hasbrouck explained all this as part of documenting and opposing the airlines’ desire to move to personalized pricing. Instead of acting as common carriers and publishing tariffs that apply across the board, with personalized pricing the airlines would use the information they have about you to charge what you can and would be willing to pay. In 2012, the International Air Transportation Association called it “New Distribution Capability”.

This is a much scarier proposition now than it was then; companies have a lot more data they can exploit. In 2012, they might simply have known your flying habits and credit score, while balancing their desire to get the most they can for the seat against the time they have left to sell it. Uber uses similar tactics; it raises the price of a ride – “surge pricing”, or “dynamic pricing” – when demand is high.

Today, an airline might know – or be able to find out – that you are racing against time to see a beloved relative before they die. And why should it stop with airlines? Exploitative possibilities abound.

Uber has already been dubiously accused of charging more when riders’ phone batteries are low. Retailers collect shopping histories through loyalty cards and apps; often customers already pay more for opting out.

Some types of price discrimination have long been illegal under consumer protection law. On February 12, US senators Ben Ray Luján (D-NM) and Jeff Merkley (D-OR) introduced the Stop Price Gouging in Grocery Stores Act of 2026 to block it in grocery stores. Other efforts are also underway in the US. This week’s news is calling this “surveillance pricing” or “predatory pricing”, which accurately reflects the data collection and surveillance capitalism underpinning.

This is not really a story about specific technologies, although “AI”; the issue is, as Hasbrouck writes, opacity and discrimination.

The technological pieces are in place to make this all much worse. Not just online, where prices are easily generated on the fly, but also in real-world retailers via wireless connections and electronic shelf tags, which already exist in some stores. A May 2025 study finds that these tags are so far not used to implement surge pricing but to update sale prices and offer discounts – but for how long?

In a May 2025 paper in the International Journal of Research in Marketing researchers examine the rise of algorithmic pricing – Uber, landlords, retailers – generally and personalized pricing in particular. The authors note that the latter requires market power, and buyers must have limited ability to exploit price differences. And also: it’s profitable (duh). The authors go on to discuss the role of privacy, data protection, consumer laws, and backlash, in curbing unfairness. At Big, which focuses on consolidation and market power, Matt Stoller warns of the potential power of Google’s plan to run pricing strategies for advertisers.

Hasbrouck returned to the subject last year while recapping the latest season of The Amazing Race to explain the airlines’ use of systems that deliver increasingly opaque and unpredictable pricing and the lack of enforcement enabling it.

In a pair of posts, the ACLU’s Jay Stanley follows Hasbrouck’s logic to new levels, laying out a possible future these developments may bring. The desire to wring every last possible bit of profit out of us – we’re talking everyone who sells goods or services now, not just airlines – in Stanley’s view will lead to collecting more and more detailed data. The digital identification infrastructure being built into airports – as planned here in 2013 and shown arriving in 2022 – will ensure there is no countermeasure we can take to escape monitoring and data collection. In Stanley’s projection, stores will be able to demand a digital identification sign-in as a condition of entry.

Again, a bit of this is here already. In the UK, Facewatch, which we first encountered in 2013, is used by some major retailers to identify and bar shoppers who have previously been caught shoplifting or being violent. Recently, the system flagged a shopper and staff ousted the wrong person, who found it difficult to prove the mistake.

In other words, all these technologies, wrapped up together, could enable a world not much different from that imagined by Ira Levin in his 1970 book This Perfect Day, where everything anyone wanted to do required permission from a centralized system. Although: the key to making that work was drugging the entire population.

Illustrations: Burmese python in Florida, 2011 (via Wikimedia).

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.