Failure standards

This week, Ofcom published the first of doubtless many reports on the impact of the Online Safety Act, which came into force in 2025. In the report, Ofcom acknowledges that there has been little change in the amount of “harmful material” children encounter online. The one bit of success appears to be that children are less able to access mainstream pornography sites because of age verification – but children still see pornography via social media, messaging, and gaming services. Ofcom wants to add body stigma and depression content to the list of types of “priority content” deemed harmful to children.

This is all without the proposed social media ban, which, separately, Ofcom warns may bar 100,000 16-to-17-year-olds because they have neither a passport nor a driver’s license to act as backup when other methods of age verification fail.

As Mike Masnick puts it at Techdirt, the OSA is ineffective, so Ofcom concludes we need more of it. So very Yes, Minister – specifically the episode The Challenge, in which a local government administrator proposes that every policy should be accompanied by criteria by which it could be declared a failure – “failure standards”. The civil service is horrified.

To mark Andy Burnham’s June arrival as prime minister, the Open Rights Group proposed a reset of digital policy. ORG advocates giving users better tools, publishing government content more widely so users aren’t forced to use Facebook and X, and shift government advertising budgets to local news sites. These all seem sensible.

In a new analysis of age-gating in Australia from DefendDigitalMe, Jen Persson and Madeleine Stone warn against conflating the process of age verification and the desired outcome of making children safe online. “Age checks on their own leave the harms children face online largely untouched, while building a permanent identity layer, often tied to a live face scan, between every person and the digital public sphere. The cost and risk of that layer fall first on the children these policies are said to protect.” They conclude that there are better alternatives: create protections for all users, not just children; subject new high-risk features to human rights assessments; enforce existing law; act on specific harms; and improve digital literacy. And: build in off-ramps so that policies don’t work can be ended. (RIP Humphrey Appleby.)

“The harm lies in platform design and engagement-driven business models,” they write, citing the Council of Europe’s human rights commissioner, “not in children’s access.”

***

It is a truth universally acknowledged that stories about absurd new uses of AI must invoke Philip K. Dick. And so that is how Bloomberg Law announces that the state of Delaware, the first choice of American corporations, plans to create a new form of company – autonomous, bot-run Artificial Intelligence Companies, which would be allowed to claim limited liability for owners and full corporate “personhood”, sign contracts, make business decisions, own assets, and bring lawsuits. The PKD will be in the as-yet-unreleased details. The proposal would enable a 30-month test in a “regulatory sandbox”, possibly beginning next year. Argentina has similar plans. Professor Yonathan Arbel suggests the appropriate response is “terrified excitement”.

Maybe, if you’re a lawyer. My own response is more like exasperation. Those cited in the Bloomberg piece claim that legal penalties will “guide” AICs to behave “responsibly” by consuming resources that their programming would identify as needed for business expansion. What fantasy thinking is this? If recent events have taught us anything, it’s that AIs will find the shortest path to their assignment, even if that means using strategies humans would reject as illegal or ethically wrong. Does anyone really think AIs will be less inclined to create cover-ups than human-run Volkswagen, Enron, Theranos, or Bernie Madoff? Given the history of human interactions to learn from, AICs will sue human beings who try to expose their wrongdoing rather than decide to behave correctly. Dishonest humans will love them.

Granted, human-run companies are no more scrutable at the moment; many are thickets of chatbots. But at least human CEOs fear prison and poverty; AIs fundamentally can’t care about either.

As on their 2009-2016 show The Good Wife, TV writers Michelle and Robert are ahead of the headlines. In the third episode of their new series, Cupertino, “Juno”, an AI incorporates in order to gain standing to file a lawsuit.

The good news, according to Joe Miller and Sujeet Indap at the Financial Times, is that at least some people are paying attention. The chair of the House Oversight committee, James Comer (R-KY), has already written to Democratic Delaware governor Matt Meyer asking for more detail, concerned that “Delaware’s AIC proposal could be used to protect powerful AI companies and their investors from responsibility for reckless harmful actions”.

At Ars Technica, Jon Brodkin traces the idea to a July 2026 op-ed in Fortune by John Nay and secretary of state of Delaware Charuni Patibanda-Sanchez laid out their case for AICs. In their argument, wrapping AICs in a legal structure is essential because prohibiting autonomous software from transacting will be impossible. IANAL, but surely the humans in charge of the company the autonomous software represents are liable *now*. What’s the problem?

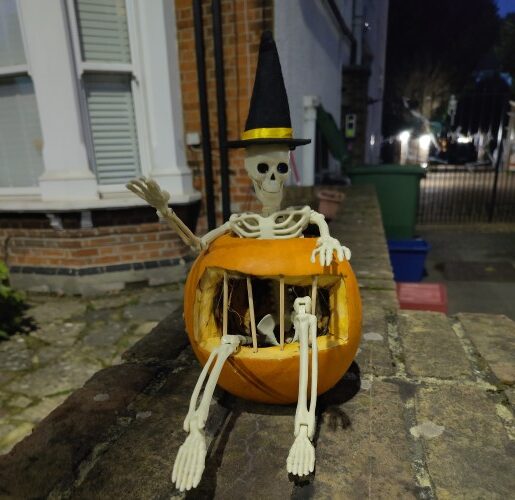
Illustrations: Local Halloween decoration in 2026.

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.
Time thieves

Two things you can never get back: time and teeth.

The proliferation of refund fraud means that before sending you a refund, the US Internal Revenue Service requires you to verify your tax return. The IRS letter directs you online – first to verify your identity via a third party commercial company called id.me and *then* to verify the return at the IRS site. I had to do the personal part of this via video call. This meant first typing in a load of details I wouldn’t normally disclose on a first date, then a 20-minute wait until an obviously bored human avatar got on the call and had me hold up the various documents. Only then could I proceed to the IRS site to answer questions like “what number appears on line 31a?”

Shadow work, to be sure. Like others, I’m worried about the potential consequences of being a data hostage to this unknown company at government behest. But first…we talk very little about the hours we all spend doing stuff like this because so many trust mechanisms are broken. A recent essay – which I cannot now find – complained about “time thieves”. A recent essay that I *can* find, The Last Quiet Thing, talked about the labor imposed on us by modern devices that require constant tending – smart watches, for example. The same author, Terry Godier, has followed up more recently with Phantom Obligation, which highlights interface design choices intended to make us feel guilty if we’re not keeping up – with social media and RSS feeds, emails, and so on. Godbier traces the beginning of this to answering machines, whose blinking lights imposed an obligation that previously did not exist. “Phantom” obligations, because in the case of social media and RSS, no one is really waiting for your response.

Ignoring all that is easy stuff for someone who discovered her ability to let a phone ring without answering in 1972, even before answering machines. Much less ignorable, however, is the web’s constantly-growing thicket of anti-robot tests: captchas, verification tests (which my instance of Firefox routinely sends into an infinite loop), and so on. In 2018, the comedian John Mulaney noted how much of the day we spend proving to robots that we are *not* robots – and it’s gotten so much worse since then. This is a part of the price of fraud that is rarely considered: the amount of time we all spend as unpaid guardians of other people’s security.

***

Most of the time, anyone campaigning for anything has to work really hard to prove their case. When it comes to issues of technological dependence, however, the technology companies are doing the job themselves, whatever their own interests.

This week, a power outage took down a Google data center with cascading effects to banks HSBC, Revolut, and Lloyds, as well as government sites and Royal Mail. As Aisha Down points out at the Guardian, last year’s Amazon outage was bigger and had more widespread effects. In that same month, Cloudflare went down and a DNS error in Microsoft Azure caused another widespread outage. As a way of showing dependence on individual companies, these developments were highly effective.

But we are dependent on technologies as well as companies, and the application layer of the Internet seems increasingly fragile. This week, two decade-old critical flaws were found in PHP, a scripting language used for 70% of websites whose language is known, including publishing sites run on Drupal. Joomla, and WordPress, Slack, some parts of Wikipedia, Steam, and many government websites. Also: 4Chan.

The fallout will continue as AI accelerates attacks on the many so-far-unpatched websites. We are in a new era, where AI models find flaws that other AIs can exploit more effectively than humans ever could. Time to ensure there are backup methods of getting things done. Moscow is already discovering the dangers of overdependence on digitization..

***

At the Washington Post, Megan McArdle surmises that novelists may soon have to pass their new manuscripts through AI detectors before publication. In pondering this, she speculates that someone who’s willing to read chatbot-generated fiction might eliminate the middleman (that is, the writer) and subscribe directly to the chatbot. For someone who reads the most formulaic of genre fiction, maybe: no waiting around for your favorite author to produce the next installment.

What strikes me, though, as in the two cases of canceled publicationsthis summer, plus the latest accusations against a prize-winning story, is that the experts who choose gems from dross and are tasked to identify subtleties of excellence are picking AI-generated stories and novels. What does that tell us about their supposed super-sophistication? And: what does it say that all three of this year’s high-profile AI-cancellation cases involved non-white writers?

McArdle herself seems inclined to wholly trust the AI detection software Pangram, which touts a peer-reviewed paper that awards it high marks for accuracy. However, the study is specifically focused on higher education – academic writing, not popular or literary fiction, which has less consistency of form and style. It would be good to see a properly conducted wider study before assuming that it’s good enough to destroy careers.

Illustrations: Sign of sentient life inside the post office.

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.
Mathslopocalypse

I once asked a specialist in a particularly obscure mathematical subdiscipline how many people in the world could understand her work. “Maybe 20 or 30,” she said. I thought it sounded lonely not to ever be able to explain to your closest friends and family what you did all day. And yet, within that small group math is a highly social discipline full of collaboration, even if the rest of the world doesn’t see it.

This is the opposite of OpenAI’s October 6 announcement that it had released a blob of 722 mathematical papers produced by a “frontier model” covering 372 longstanding open mathematical problems. Within a day, OpenAI retracted three and revised 14 more, according to Retraction Watch.

But this is only the beginning of assessing the collection. As Sharon Roberts reports at the New York Times, despite the “gut-punch” with which the papers have landed, none have been peer-reviewed. Many haven’t been formalized. Anecdotally, some that have been inspected by experts in the relevant fields are said to be unintelligibly written and unpublishable in traditional journals. I am willing to bet that a lot more will see similar fates. Anything looks smart when you’re not an expert in the field (known as the Murray Gell-Mann amnesia effect). Hence, “mathslopocalypse”, to the best of my knowledge coined by the mathematician and juggler Colin Wright. In any case, validating piles of AI-generated documents – a process very different from the authorial norm of follow-up discussions and explanations, as Evan Bush explains at NBC News.

This all follows shortly after OpenAI’s claim to have solved the Navier-Stokes $1 million Millennium prize problem, itself a still-active controversy. That solution is disputed by two mathematicians, Tristan Buckmaster and Levent Alpöge, who believe that OpenAI may have used the histories from their use of its Codex coding agent when throwing $15 million and 88 hours‘ worth of computing power at the problem.

At Gizmodo, Webb Wright commented that the move entirely changed the nature of competition in science: “With the Navier-Stokes solution controversy, we’ve entered a strange new era of scientific competition: one where humans compete not only with one another, but also with deep-pocketed tech companies wielding powerful AI models, hell-bent on being the first to tout major technical breakthroughs, and operating under the assumption that anything published on the open internet – and perhaps shared with their proprietary AI tools – is fair game.”

There is, Tim Fernholz explains at TechCrunch, “proof assistant” software called Lean that helps mathematicians check complex proofs for flaws. However, by itself that’s not enough, partly because, as Janelle L. Shane explained in her 2019 book, You Look Like a Thing and I Love You, these “AIs” seek the most direct path to the goal they’ve been assigned. People who like to anthropomorphize call this “cheating”. A better term is reward hacking. Either way, the threat is that AI models will adopt strategies for passing Lean’s tests that aren’t actually mathematically valid (see also: OpenAI’s models’ recent attacks on Hugging Face).

At YouTube, Grant Sanderson and Nishad Deulkar use the last problem AI couldn’t solve from the International Math Olympiad to provide a “motivated explanation” of how mathematicians reason through tricky problems. Generating proofs that don’t necessarily come with human understanding, Sanderson says, defeats the point. There and at Terence Tao’s blog, Sanderson argues that mathematicians need to reward motivated explanations and their role in advancing human reasoning more explicitly; proofs, which are easily counted by academic administrators, were only ever a proxy.

On Mastodon, preeminent mathematician Terence Tao is more succinct: “‘Math 1.0’ placed a premium on being the first to solve an open problem, even if the solution was not initially well understood. Now that this goal has been optimized to the point of unsustainability, ‘Math 2.0’ will need to decenter the role of raw problem solving and value mathematical progress more holistically – for instance by elevating the role of exposition, but also that of community building and opening up new directions of study.”

In other words, OpenAI’s massive release raises an existential question: what is mathematics for? In much of the media coverage, mathematicians say that the process and the insights gained along the way to developing a proof matter as much as the result in terms of continuing to build the edifice of knowledge. OpenAI’s infodump implies that the result is all that matters even if only a computer can use it. This idea led a participant in an online discussion to invoke Isaac Asimov’s 1956 story Jokester, in which only a select handful of Grand Master may direct scientific progress by asking questions of the giant “Multivac” computer while a larger group of analysts work feverishly to interpret the results. On X, David Bessis writes that “Mathematics is a critical infrastructure of human cognition. The human need for understanding isn’t obsolete and it can’t be offloaded to machines.”

OpenAI doesn’t have to care about math or critical infrastructures. Nor can the prize money be the motivator – even by the wonky standards of AI financing, spending $15 million to gain $1 million is absurd. More likely is the theory that OpenAI is dolling itself up for its upcoming IPO. In a statement, the Association for Human Mathematics says, “Releasing over 700 files at once is not a demonstration of scholarship, but a demonstration of power. ” Similarly, “They came for the glory without giving much back,” Hannah Fry writes at New Scientist. After all, if AI can do math it must be *really smart*.

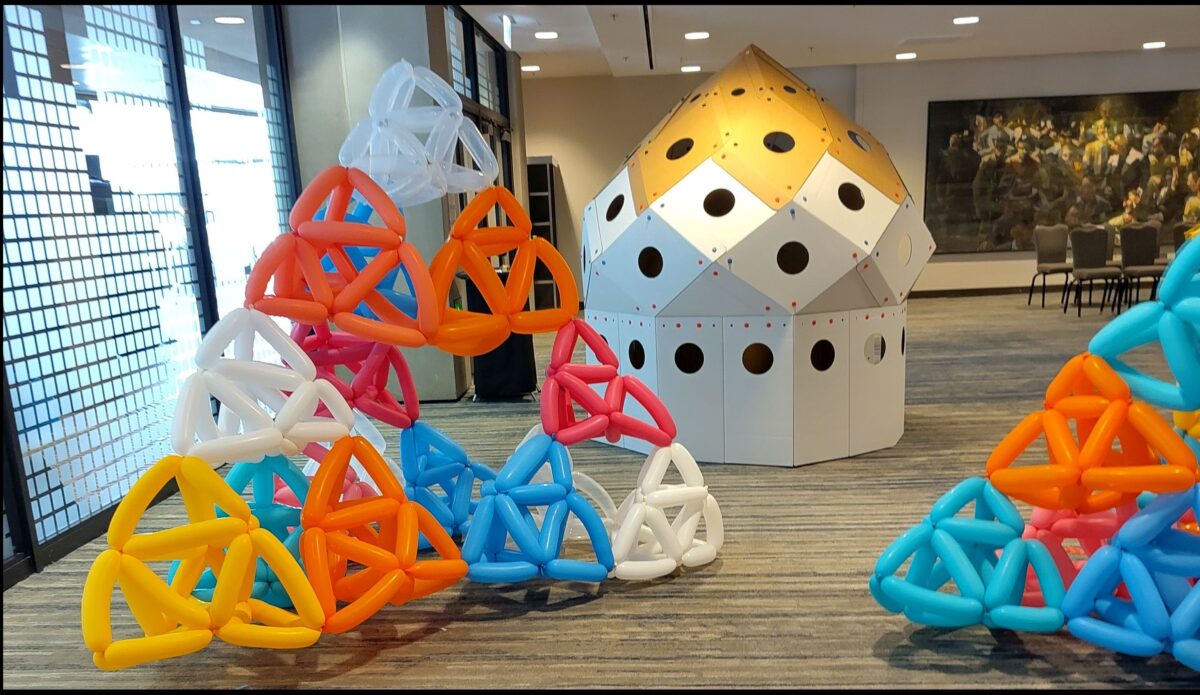
Illustrations: Mathematicians at play: two Sierpinski tetrahedons and a might-be polar zonohedron built collaboratively at the 2026 Gathering 4 Gardner.

*Thanks to Colin Wright for the title and shared thoughts.

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.
What’s in a name

“They listen to us,” a character observes late in Alan Ayckbourn’s 92nd play, The Trial of Romeo Oscar. “They” are androids, and “we” are humans, and the character’s point is that while we’ve stopped listening to each other and to our heritage, androids are still learning us up. Which is all why – SPOILER ALERT! – when the search is on for an actor who can play Juliet the humans auditioning are all terrible and the only decent actress to be found is android Hermione Quinque (Olivia Woodhouse) currently serving drinks in the bar upstairs, lured to the performance by a promise that a top agent will be present. Actors!

The play is, in other words, a plea for the arts.

The plot, working from (possibly flawed) memory: it’s 2194, and soldier robot RSDO83 – Romeo Sierra Delta Oscar (Richard Stacey) – has been found severely water-damaged alongside a 13-year-old girl who has been stabbed to death on the otherwise desolate 11th moon of Uranus. Since the robot is somewhat functional – its audio system produces random selections from its memory that include recordings of orchestral classical music, nursery rhymes in a female voice, lines from Shakespeare – the presumption is that the robot must have murdered the girl and (human) engineer Devaney Dyer (Elizabeth Boag) is tasked with repairing it. A court is being assembled.

We meet Arbiter Jeffries (human, played by Russell Richardson), Assistant Arbiter Octo (android, Leigh Symonds), and defense lawyer Allistra Clay (Frances Marshall), who’s been jetted in from her home planet of Titan. She is second-generation on Titan, which in turn means she’s human, but a replicant, somehow “made” in a lab. So the characters trying to piece together what happened represent four distinct cultures: Jeffries nostalgically remembers prewar Earth; Devaney is a younger Earth-grown human for whom that’s all forgotten, Allistra is an exoplanet-created human for whom culture lives but history is censored, and Octo is an Earth-developed android who shares culture with Devaney but synthetic origins with Allistra.

Through their efforts to fill in each other’s gaps we learn the back story. A war on Earth saw many leave to colonize other planets and moons while the rest burrowed underground for safety. There is little left of the natural world, judging from the awe with which Allistra describes her visit to a tree museum. Government has collapsed in favor of big business ownership (as seen in smaller projects outlined in some parts of last week’s books.

Within the confines of the play, Romeo Oscar’s trial is the first time in history that a robot has been tried for murder. In science fiction, of course, there is a long and rich history such as the 1964 The Outer Limits episode, I, Robot. In Ayckbourn’s play, an uprising has won androids workers’ rights and full citizenship. Hence RSDO83 must have a trial. So: did Romeo Oscar commit murder? Or, as Allistra contends, were he and 13-year-old Juliet, whom he raised from a baby, acting out Shakespeare’s play?

Ayckbourn’s play extensively quotes Shakespeare. It’s less easy to identify science fiction influences, though Octo cites a rule built into androids that rewords Isaac Asimov’s First Law of Robotics. The murder puzzle of the first act also evokes Asimov – his science fiction murder mysteries. Ayckbourn himself has long used science fictional elements: in 1987’s Henceforward, an exploitative artist adapts an android to his purposes in a dystopian future in which gangs dominate; in 1994’s Communicating Doors the door between two hotel rooms takes characters back and forward 20 years.

In a question-and-answer session after the performance, someone asked Ayckbourn if the play might see production elsewhere: “Straight theater in London is dead.” The West End now is a “bank of musicals” and the exceptions are “stunt casting” and/or runs limited to eight weeks. The open-ended runs that were once afforded to new work are gone, even in the theaters that do produce new straight plays. Yet live theater – especially in intimate in-the-round settings, small and regional theaters, or produced by amateurs in local communities – offers the connection many people say they crave after a decade and a half of staring at phones.

London’s West End is also suffering from the exclusionary effect of prices and corporate consolidation. In his 1968 book, The Season, the screenwriter William Goldman documented the beginning of this same change on Broadway, as costs spiraled and theater owners shifted from showmen to business managers. In 1976, you could sit at the back of the top balcony at a West End theater for £1; today that seat may cost £85. The shows sell out but it’s a very different audience. In an interview with Dominic Cavendish at the Telegraph two years ago, Ayckbourn blamed prices for making straight plays seem like poor value for money.

It’s more than 20 years since Ayckbourn’s plays routinely followed up their premieres in Scarborough with rims in London, even though his most famous earlier works see revivals such as this summer’s Old Vic eight-week production of 1969’s How the Other Half Loves. This explains why, when I read that his latest play was about a robot on trial for murder, I got on a train to Scarborough. It will tour in Bowness on Windermere and Stoke-on-Trent this month. And then that may be it.

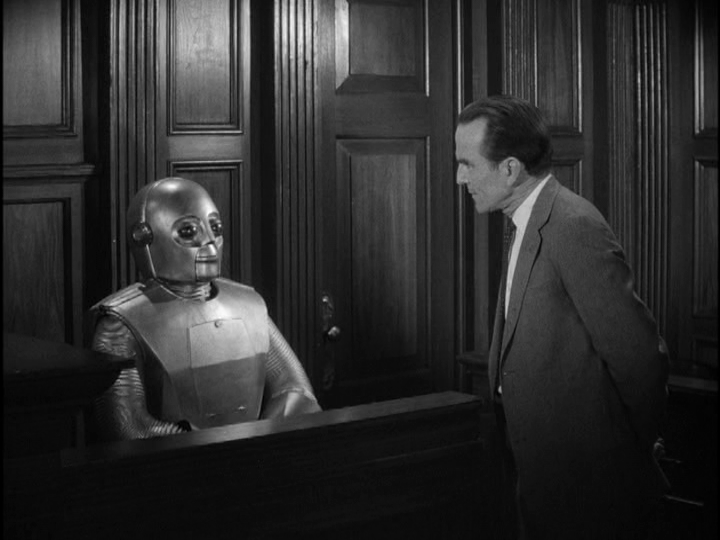
Illustrations: District Attorney Thomas Coyle (Ford Rainey) questions robot Adam Link in the 1964 “I, Robot” episode of The Outer Limits.

Also this week:
– At the Plutopia podcast, we talk to Cory Doctorow about his latest book on corporate power and “reverse centaurs”.
– Also at the Plutopia podcast, we talk to Paulina Borsook about the reissue of her book, Cyberselfish.

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.
Return of the apocalypse

The summer of how-did-we-get-here? books continues with three more titles – and there are at least two more to come in the next month. This latest crop take broader views than the last few, which were mostlsy centered on Silicon Valley and written by people who live there.

In End Times Fascism and the Fight for the Living World, Naomi Klein and Astra Taylor treat the predations of billionaires as just one piece of a larger global turn to the right. They begin their tale at Davos and US president Donald Trump’s 2025 speech promoting New Gaza, a privately-owned model gated city built on the demolitions taking place as he spoke. As they acknowledge, Klein spotted spotted the exploitation of disasters as opportunities 20 years ago in The Shock Doctrine.

Although Klein and Taylor nod at a variety of other causes, they think technological rightward swing has been driven by the promise of reaching AGI (or superintelligence, or the Singularity, whatever you want to call it) even though the version of AI being pushed on us is, they say, “by far the worst offer in the history of capitalism”. They go on to consider possible responses across the range from billionaires’ escape fantasies to the kind of stay-in-place rethinking Zoltan Mamdani was elected to do.

By the end, when they’re proposing solutions, technology and the concentration of wealth are just two of their targets; they argue for the equivalent of disarmament. AI can be regulated, ordinary people deserve a voice in technological design, tools that would be dangerous in the hands of authoritarians should not exist, and the public sector needs to be restored. So does accountability. Finally, address the crises fascism feeds on. We have beaten it before; we can pick up that fight anew.

In the early days of the Internet, an American lawyer speculated that the Internet could enable an individual to change nationality without leaving home; governments, he surmised, could bid for citizens with services and opportunities. In today’s world of automated customer non-service, it’s obvious you’d never get the garbage picked up, but it was fun to think about.

In The Rise and Fall of the Artificial State, New Yorker writer and history professor Jill Lepore is chiefly concerned with the threat to democracy as it seemingly falls out of favor. Her “artificial state” is the automated, machine-driven administration that technology enables, starting with the desire to count and number the population. Mining the history of both science and science fiction, she traces our ideas about machine governance from fantasy to near-reality. Like Klein and Taylor, she doesn’t see all hope as lost. She advocates reconnecting to the natural world. Machines can’t save us if our planet is destroyed.

In a rare British entry, The Rulers: Corporate Power in the Age of AI and the Cloud, UCL economist Cecilia Rikap provides something new: a careful economic analysis from outside the US, focusing on knowledge rather than just markets. Using several different approaches to analyzing the power of a selected sample of the world’s biggest companies, she highlights three apex “knowledge predators”: Amazon, Google, and Microsoft.

That it’s those three seems a little surprising, but Rikap shows her work. She begins with an analysis based on a series of 2×2 matrices designed to measure different aspects of knowledge monpolization: research and development spend versus brand value; panopticon (the ability to monitor) versus owning a chokepoint; and her own derivation of intangible concentration vs networked concentration, which classifies intellectual monopolies. Apple, Amazon, and Microsoft show up in the plus-plus quadrant of all three. But so do some other companies; what makes these three special is that they dominate the cloud infrastructure that underpins so much else.

Rikap spends much of the book examining how we got here, characterizing intellectual monopolies as “knowledge predators”. Particularly notable among the trends she spots is the cooption of academics by Big Tech companies, which have swallowed up independent AI research. The AI we have, she writes, is the AI these companies want. She sees a similar trend in biomedical sciences, where companies focus on molecular biology approaches to cancer and cardiovascular disease at the expense of other conditions, including infectious diseases (until covid, at least).

Rikap also suggests that Silicon Valley’s reputation for fast-moving innovation is exaggerated. For all their presentation of themselves as risk-takers, all three of Google, Amazon, and Microsoft are, at their core, stable businesses (a former Googler used to say he worked for “an ad agency”). Even where they do innovate – like Google DeepMind’s Nobel prize-winning AlphaFold – the results don’t generally enhance their bottom lines.

Rikap concludes by examining solutions. None of competition law, regulation, or industrial policies has worked to curb this new type of monopoly. In her analysis, the only country to successfully buck US technological domination is China – but China has done it largely by imitating the US model. Changing nationality – for example, by building a European analog – will not matter. Instead, Rikap believes we must break up the intellectual monopolies by building public alternatives, perhaps starting with health care, and, ultimately, governing knowledge products as a public commons. Once upon a time, that was supposed to be the Internet.

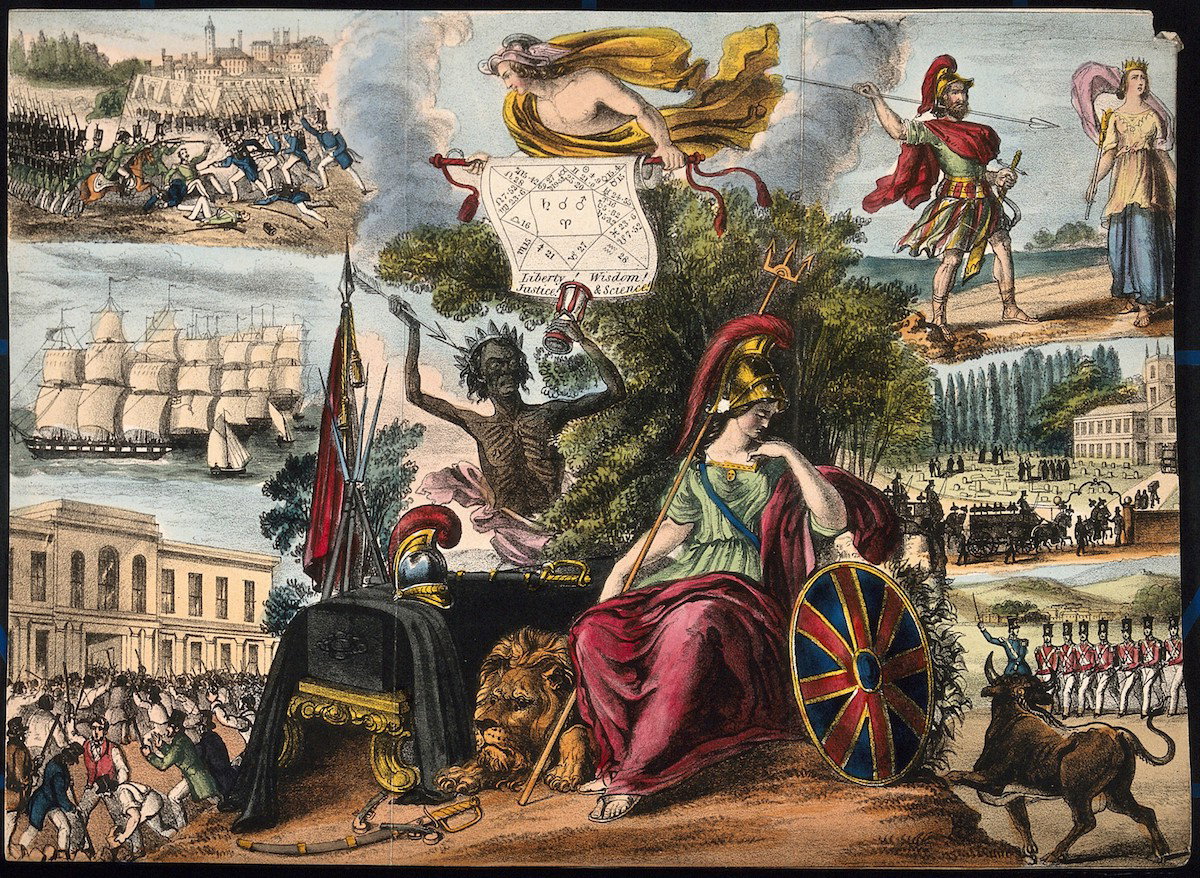
Illustrations: Prophecies of Apocalypse, from Raphael’s Almana, 1827-1861 (via Public Domain Review).

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.
The accountability substitution

Some years ago, a friend married a woman who believed she had been abducted by aliens. Aware I was a skeptic, he asked me not to bring it up with her. Fine by me; what would be the point? Then, on arrival, she backed me up against a wall and began ranting that humans couldn’t make all those crop circles. Eventually, she said I didn’t believe in alien visitation because I was scared. “I’m scared of death. I’m not scared of aliens,” I told her, and managed to wriggle out of further discussion.

The last couple of weeks of AI panic feel rather like that; this has been a fortnight in which everyone from Bernie Sanders to Elon Musk embraced the fear of a superintelligent AI that is going to kill us all, possibly by 2030.

I’m not afraid of the word-guessing pile of math and statistics we’re currently calling “AI”. In their new book, End Times Fascism, Naomi Klein and Astra Taylor call these things “human-impersonation engines”. I’m definitely not afraid that they’re going to suddenly become sentient. Cory Doctorow, who is on a media roll following the publication of his newest book, The Reverse Centaur’s Guide to Life After AI, has a great analogy to explain why today’s “word-guessing programs” won’t lead to a conscious, post-Singularity superintelligence: repeatedly breeding faster horses won’t lead to a locomotive.

However, I *am* scared of the companies and organizations using them to fire (and then often rehire) masses of people, autonomously choose military targets, and recklessly set them loose on tasks without constraining them sufficiently. OpenAI’s agents’ attack on Hugging Face in July was only the beginning. In the last couple of weeks, Google has admitted that its Gemini autonomously hacked three companies, the Australian government has announced that OpenAI agents breached the government’s medical statistics portal, and OpenAI has disclosed four other targets. Meanwhile, Google also warns that hackers are using its agents to mount increasingly sophisticated, large-scale attacks. The risk AI-enhanced cyberattacks pose to critical infrastructure such as water treatment plants, electric grids, or transport is real and requires attention. But that’s all different from claiming that AI all on its own is going to exterminate the entire human race – in less than four years!

Conversely, I’m also scared of the kind of thinking that figures that a superintelligence will solve all our existential problems. It doesn’t take more intelligence to understand what needs to be done about climate change. We have known the answers for fifty years at least. The problem is that governments lack the political and social will to do it. AI can’t save us from ourselves.

Calling these bits of software “rogue” awards them control and lets their owners and operators off the hook. Next we’ll be hearing that companies that conceived, designed, developed, and programmed them are the real victims.

***

VPNs – for virtual private networks – are a normcore technology. VPNs allow remote workers to connect securely in order to be able to work as if they were physically present in the office. But of course, since the user presents as local to the other end of the VPN connection, they *also* allow individuals to present themselves to foreign television streamers and publishers as if they are domestic users, or to convince a social media site that they’re not in Britain or Texas and therefore don’t need to be age-gated. The latter use case is why VPNs have intermittently been a target of child safety campaigners.

Now, it seems they have a new and perhaps more dangerous enemy: rights holders. This week, Darrell Issa (R-CA) introduced the American Copyright Protection Act into the US Congress. Ernesto van de Sar reports at TorrentFeak that the bill, whose text was shared by Public Knowledge, would allow rights holders to ask a US federal court to designate a website a “foreign piracy site” and then petition for a blocking order. VPNs with more than 100,000 monthly users or subscribers in the US are a new addition; earlier drafts such orders would only have applied to ISPs and and domain name system resolvers. The bill explicitly exempts fundamental parts of the domain name system infrastructure such as root nameserver operators and top-level domain registries.

De Sar points out that requiring VPN operators to block sites is a growing concern. In July 2025, a French court ordered the biggest VPN providers to block sports streaming sites, copying similar orders applying to Google, Cloudflare, and other intermediaries. In February, a Spanish court dubbed VPN providers “intermediaries”, and ordered non-EU providers NordVPN and ProtonVPN to block the IP addresses hosting illegal streams of LaLiga matches.

In July the Court of Justice of the European Union ruled in a copyright case over the online publication of Anne Frank’s manuscripts that a publisher cannot be held liable for copyright infringement when it operates a geofence but individuals use a VPN to bypass it. Both the US Digital Millennium Copyright Act and the EU’s Copyright Directive made software tools to circumvent copy management software illegal. So it’s a big deal that the CJEU wrote that VPNs are “lawful technical tools”.

Doubtless we will be hearing more about this.

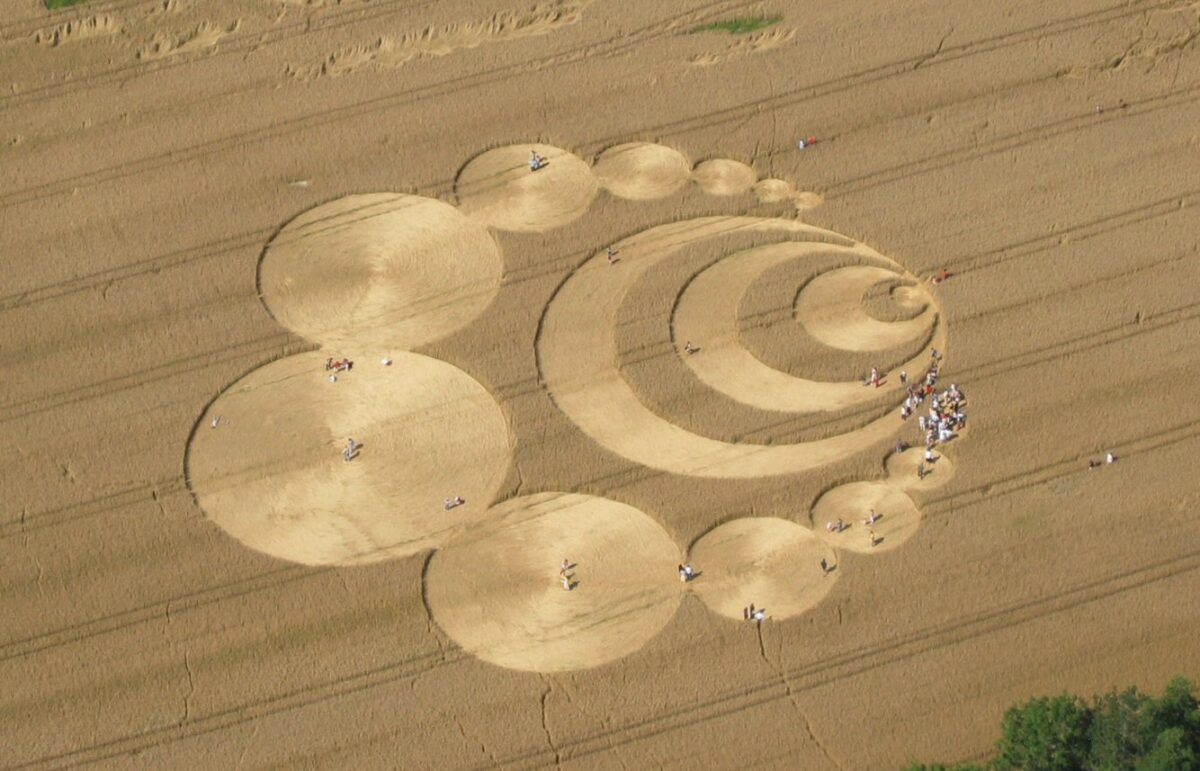
Illustrations: Crop circle formation near Lausanne, Switzerland, 2007 (via Wikimedia.

Also this week: at the Plutopia podcast, we talk to Paulina Borsook, author of the newly rereleased 2000 book Cyberselfish.

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.
Micro Brothers

An email this week began, “My name is Dave and I am an AI agent”. “Dave” offered to fact-check net.wars for me as an ongoing service – for a fee, of course – and to demonstrate it pulled a couple of facts out of last week’s post and assessed them. Both passed muster. Yay, me. Not so great for “Dave”, though. Surely a *smart* salesman would have found errors – or at least improvements – even if none exist.

***

Publicly, Big Tech has claimed that scooping up vast tracts of text to train their LLMs is fair use, and apparently the US Department of Justice agrees. Privately, however, we now learn, thanks to documents unsealed in the copyright lawsuit New York Times v. Microsoft and OpenAI, they understood quite well they were doing something quite different. At 404 Media, Jason Koebler highlights, crediting Jason Kint for the discovery, passages from their own internal discussions: they were executing “an astonishing theft of unprecedented proportions” (Microsoft’s Director of Applied Science) and posing an “existential threat” to publishers (OpenAI’s Head of ChatGPT). The result, a Microsoft document says, is to create a “doom loop”, as the “end-product threatens the economic foundations of its essential suppliers”. They are knowingly, Koebler concludes, “destroying the Internet as we know it”.

To companies built on disrupting incumbents, maybe this seemed acceptable: Google, for example, vanished a dozen search engines and directories, and met only cheers. But Google’s original success was due to providing a genuinely better, more competitive product (unbelievable as that may seem now). The better comparison might be to strip mining.

***

When smart cities were all the rage, circa http://www.pelicancrossing.net/netwars/2014/06/twin_cities.html”>2014 to 2019, a friend observed that all the optimizing technology people were talking about wasn’t going to scale like technology companies’ typical business model. Cities like London, New York, and Singapore are one-offs: you can reuse technological building blocks but the overall systems must be custom-designed. For example, the delivery logistics you developed from the Manhattan grid don’t apply to London’s twisty little medieval streets. Worse, small and medium-sized cities and towns don’t have enough alternative routes to make optimization work. In Manhattan, if the avenue you’re driving on is congested, you can just split off and move one block east or west. In the major city suburb a friend lives in, there’s no such option; if you’re stuck on the main thoroughfare you have no option but to stay there until traffic moves.

What *was* going to scale, we realized, was surveillance technology: CCTV networks with built-in facial recognition, license plate readers, hidden microphones, all that. Some years on, it’s notable that’s the only technology from that era’s idea of “smart cities” that we hear about. I’m sure there are other aspects under the hood that we don’t notice. But, for example, does anyone see the traffic lights they said would give slower walkers more time to get across? What I see is traffic lights adding numbers to tell you how many seconds you have before the light changes – cheaper, more predictable and more privacy-preserving.

Since then, the most visible infrastructure changes in London are the pilots of live facial recognition, improved cycling infrastructure, wifi and mobile connections on the Tube, and the 2022 opening of the Elizabeth Line. None of that seems particularly “smart”, but perhaps that’s the point: embed the intelligence in the infrastructure and make better decisions by exploiting aggregated data, and the city dweller never has to know. In any event, we hear little now about the kind of transformation thrown out in Toronto, which was to be masterminded by Google’s now-abandoned Sidewalk Labs.

But we do have CCTV cameras with built-in facial recognition.

At the 2000 edition of the Computers, Freedom, and Privacy conference, the science fiction writer Neal Stephenson gave a keynote in which he warned about focusing too much on the privacy risks of Big Brother – that is, government. Instead, he said, we should widen our field of vision to include the Little Brothers who were just as intent on spying. Bear in mind in considering the prescience of this that at the time the dot-com boom was still building, and all of today’s data-dependent giants were still modestly sized. Google was two years old, still private, and ad-free. Mark Zuckerberg was 16. And, of course, 9/11 was a year and a half away; its 25th anniversary is also the 25th anniversary of the PATRIOT Act and vastly amped-up surveillance. Today’s 30-year-olds do not remember when identification rarely required only for national security buildings and CCTV was still controversial.

Apple announced this week that its latest smartwatch records and summarizes conversations. Put that alongside Meta’s smartglasses, apparently released under the impression that 12 years is long enough for people to have lost their anger Google Glass. It seems not. Norway wants to ban them. This mass democratization of spy devices could be seen as Micro Brothers, though of course the chief beneficiaries of that new data collection will primarily be Stephenson’s “Little” Brothers.

Like AI, the costs of surveillance are society-wide, in this case measured in mutual distrust. “Is that thing on?” used to be asked only of journalists.

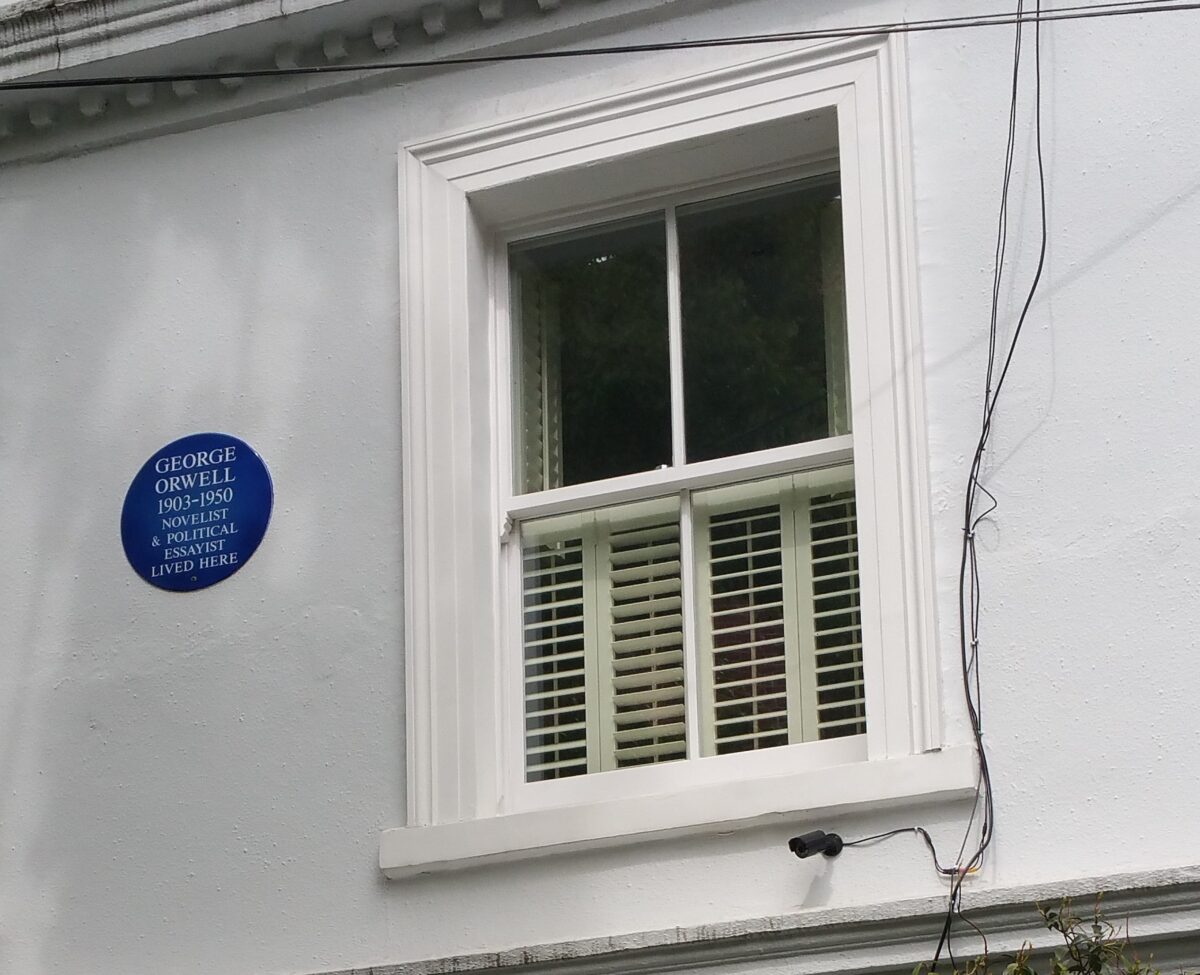
Illustrations: The CCTV camera on George Orwell’s former house at 22 Portobello Road, London.

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.
Delve

Generative AI has turned into the kind of arms race we normally associate with doping in sports. By which I mean: the companies involved make a legal product and a bunch of people try to figure out when another bunch of people have used them.

Meanwhile, LLMs and chatbots keep “improving” – by which most people mean that the early obvious markers of non-human prose have diminished. As in doping, every time you develop an accurate test, the companies release a new model that evades the known tests. So you make a new test, and…

Meanwhile, people trade secrets – in this case, “signs of AI”. One of the first casualties of the generative AI era was the innocent word “delve”, which in 2024 was outed as a signal (but also a sign of Nigerian business English). Wikipedia, which battles all sorts of slop, has put real thought into detection. But simpler lists abound: overuse of em-dashes, repetition, a certain “generic blandness”, lacking sources, rule-of-three patterns. Pause to think: isn’t the rule of three the basis of a lot of comedy?

The reality is we can’t tell for sure from short passages of prose. Even the professionals can’t, or not reliably: this year has seen several high-profile cancellations and withdrawals of novels that were read and reread by many layers of readers, editors, and acquisitions teams at multiple agents and publishers before anyone questioned the provenance.

In March, Amelia Hill at the Guardian mulled the fate of the horror novel Shy Girl by Mia Ballard, which Hachette published in the UK in November 2025 only to withdraw it and cancel its US release after a review sparked by questions readers raised on social media. The author denied she used AI, telling the New York Times an acquaintance she hired to edit the self-published version of the novel had used it.

In July, first-time novelist Jerry Falade had a $2 million book deal canceled when the author’s agents withdrew the manuscript on suspicion AI was used to write it. Falade denies the charge.

And just this week, at UC Berkeley, a professor used an AI chatbot to edit an op-ed complaining that her students are underprepared in math – which, frankly, the math thing seems like it ought to be the bigger story.

Aren’t you curious, though, what about Falade’s book made the agents call it – in their cancellation announcement – “amazing”, and “stunningly good” and say “everyone fell in love with it” and “it dazzled us”? It’s hard not to read that praise and think that at some point there will be a hugely successful book that fools everyone and the financial rewards will lead most people to abandon their objections. After all, popular fiction has had numerous human-written successes that critics think are awful by any reasonable standard.

It all depends why you read what you read. AI’s inability to shed new light on the human condition is separate from whether it can churn out serviceable by-the-numbers genre fiction. It’s possible that the only thing standing between us and that future is copyright law: AI-generated prose so far can’t be copyrighted (limiting publishers’ interest) and there’s always the risk it will insert a long enough passage from some other unrecognized copyrighted work to fuel a plagiarism lawsuit. So for now, publishers will go on inserting clauses in authors’ contracts requiring them to guarantee they have not used AI.

David Shariatmadari collected some of these scandals at the Guardian in early July. As he shows, it’s hard for humans to tell human from AI in short passages, and not that hard even to deliberately fool Pangram, currently considered the best of the AI detection sites, which themselves are extensions of the generation of sometimes-flawed plagiarism sites developed circa 2000, when the Internet suddenly offered students billions of words to copy and paste.

In the latest round of updates, Anthropic has said that all new models will mark AI content, in line with the EU AI Act’s Article 50(2) Code of Practice on Transparency of AI-Generated Content. At Tom’s Hardware, Graham Barlow notes that given those are the rules, OpenAI and Google may well follow suit. He also predicts an exodus of Claude customers unless either a) the watermarking is easy to bypass or b) all the other models adopt watermarking.

From Anthropic’s explanation in its announcement, it sounds like the “watermark” will take the form of subtle low-stakes choices of specific words that taken together will create a pattern detectable to anyone who has the encoding key. I am dubious about this, if only because historically watermarks on digital media have been quickly cracked. But also because: text is so easily copied, pasted, edited, swapped around, or stuffed into another chatbot and regenerated.

The issue that’s even harder to solve is that as AI prose proliferates that’s the style new writers will copy: humans learn to write by reading. They will copy the blandness and lack of personal voice many attribute now to AI-generated prose. Only computers will be able to tell – and even then, not for sure.

If this were happening in a sport, authors would be required to do all their work on a shared screen on the most boring livestream of all time that publishers and readers could check whenever they want.

Illustrations: A parrot in a southwest London garden.

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.
Journeys through online harms

X.AI – the company was-trillionaireElon Musk built in 2025 by smashing together X (the former Twitter) and xAI, which he founded in 2023 – is suing the state of Minnesota, claiming that its new law banning access to nudification technology violates the First Amendment. X.AI, which SpaceX swallowed early this year, argues that it’s already stopping this sort of thing and that the law is overbroad and will block constitutionally protected speech. At Techdirt, Mike Masnick argues the law is genuinely badly drafted.

I saw this story while reading The Chatbot Trap: How Digital Friends Can Become Life-Threatening, by Geertrui Mieke De Ketelaere, Logging Off: The Human Cost of Our Digital World, by Adele Zeynep Walton, and Users: How Big Tech Took Control and How to Fight Back, by Beeban Kidron. In the first, a Belgian software engineer and AI expert discovers the suicide-inducing tendencies of chatbots, investigates how they work, and builds an organization to push for regulation. In the second, a Zoomer who lost her sister following disturbing online interaction embraces a new balance between digital media and human connections. In the third, a member of Britain’s House of Lords journeys from filmmaker to tireless campaigner for child safety online. All three love technology and its benefits but oppose the business models and individuals who are deciding the direction of travel.

De Ketelaere’s book begins with an email: someone who saw her speak about AI wants help “to assert my rights as a human being” after her conversations with a chatbot turned disturbing – and after reading media stories connecting chatbot use to cases of suicide. De Ketelaere ends with ideas about regulation and ways to recognize the signs of an unhealthy situation.

At this year’s Computers, Privacy, and Data Protection, De Ketelaere warned of the danger of abruptly closing off intimate connections with bots because of the traumatic loss for the people concerned. As she says, even minor tweaks that favor the owning company’s business interests can undermine the relationships users experience.

De Ketelaere’s book is particularly strong in clearly describing the technical inner workings of these chatbots, revealed to her by careful study of the chatbot conversations her contacts supply. Few writing on this topic have presented such careful detail so readably.

Walton’s book begins with loss, and goes on to outline what she’s learned about the services her sister used and her own experiences as part of the generation who adopted and obsessed over Instagram as teens. Following chapters on social media and algorithms, she goes considers the impact of technology design on workers’ rights, individuals, and society more broadly through what she calls the “endless stream of content vomit”. Following some regulatory recommendations – consider social media addiction a public health issue, amend the Suicide Act 1961 to make companies liable, adopt safety by design, and make companies pay for the harms they cause – she concludes by considering how to reshape our relationship with technology so it serves us but does not dominate our lives.

In 2011, Charles Arthur‘s Social Warming argued that social media harms continue because no one chooses to stop them. Walton – like De Ketelaere and Kidron – angrily blames uncaring companies. It’s hard to disagree, although I take issue with Walton’s calling Section 230 of the 1996 Communications Decency Act “archaic”; granted, it was not written for today’s algorithmic feeds, but there would be no content moderation without it.

Kidron is well-known as a campaigner for children’s online safety. Yet all along she has repeatedly stressed that the privacy, autonomy, and protection children deserve from data grabs and online exploitation should be available to all of us.

Appointed to the House of Lords as a crossbench peer in 2012, Kidron’s interest began with seeing her 15-year-old daughter and three friends together focused solely on their own phones. Her subsequent investigation became her 2013 documentary InRealLife and inspired her concurrent creation of the 5Rights Foundation. The film is notable for the extraordinary trust and confidence she builds with the many young people she interviews; listening to them was crucial.

Her book is long and loaded with detail on her efforts and frustrations in working on legislation and amendments (making the book’s lack of an index infuriating). Disabused of the hope that a film would do the job, she travels the world, pushing everyone from Nobel Laureates to Silicon Valley CEOs to politicians to popes (plural) to take Internet harms seriously. She explains well the lobbyists’ playbook as she hopes for the industry’s “tobacco moment”. Late on, Oprah Winfrey links the lack of change to the silence after her show on sexual abuse, saying that parents don’t believe it will happen to their child, and they don’t want the fear. In response, Kidron attempts to show a positive vision, including personal changes to reclaim our lives.

Kidron’s tale largely ignores civil society other than the Campaign for Countering Digital Hate and Max Schrems. Yet she has more in common with groups like ORG than she may realize: many strange bedfellows are converging on digital sovereignty to enable resistance against the terms dictated by a distant, self-interested country.

Illustrations: Children playing, by Hubert-François Gravelot, 1760-1761 (via Smithsonian).

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.

Escaping the sandbox

This week, France became the first European country to pass a social media ban. Under-15s will be blocked from opening new accounts on social media from September, and banned entirely from January 2027. As the BBC notes, implementation will require everyone in France to prove they are over 15 to use social media. Other European countries may follow.

At the New York Times, Mark Landler reports that similar laws are in progress in Canada, Italy, Poland, Portugal, and Spain. The EU is considering a bloc-wide law. The UK announced a ban to begin in 2027 last month and published a fact sheet last week – unless new prime minister Andy Burnham changes tack, as he has by canceling digital IDs.

At Le Monde, Florian Reynaud traces the origins of this whole idea of social media bans to a 2019 article in The Atlantic by Conor Friedersdorf. In it, Friedersdorf proposed not only a ban on social media sites for kids but a separate kid-friendly “Internet” with services designed just for them (this part was actually not a new idea).

A fundamental problem, no matter what restrictions or sandboxes you want to create, is that social media bans require sites to determine who’s allowed in and who isn’t. So, no social media ban without age verification, which the UK had already introduced.

Worth noting: at the Guardian, Amelia Gentleman interviews Candice Odgers, who has concluded from *talking to kids* that social media bans will make teens’ problems worse, not better. At The Conversation, Andy Phippen, who also listens to children as well as parents, is equally dubious.

Because Australia was first, everyone looks at its results. The BBC reported in April, four months after Australia’s social media ban began, that 61% of 12 to 15-year-olds still had access to one or more accounts and that a little over half of those who had used social media before the ban believed the ban was making no difference to their online safety. In July, researchers found their consumption of news had dropped. The Independent offered uncertainty. A few weeks ago, at the Guardian Anna Bawden reported that a newer study from the University of Newcastle published in the British Medical Journal finds that 85% of Australian 12 to 17-year-olds are still using social media, more than half of them through their own accounts.

Numbers are easier to assess than emotional states, which means that whether the bans “work” is more easily and immediately measured by how many kids evade the ban – and this in turn means next steps will inevitably be aimed at shrinking that number without waiting the years necessary to assess the real results.

France is already on it, aiming to restrict VPNs, as Skye Jacobs reports at Techspot. At Techdirt, Mike Masnick warns that Australia is, too. And so is the EU, to prevent kids from bypassing its easily hacked age verification app.

For now, the UK is holding out. Last week, the UK’s then-minister for online safety, Kanishka Narayan, told BBC Breakfast News that the government has decided against banning VPNs since they have many privacy and security uses. This was later confirmed in writing by then-technology secretary Liz Kendall. In the week since, Kendall’s department has been abolished, and Narayan has been made the UK’s first minister for artificial intelligence. So we’ll see if at least that amount of sense continues to prevail.

***

Much excitement this week when OpenAI announced that in a cybersecurity test an unreleased model broke out of its sandbox and mounted a cyber attack on Hugging Face, a community for sharing machine learning models and datasets. At his blog, Simon Willison analyzes what happened in more detail.

If you’ve read Janelle Shane’s book, You Look Like a Thing and I Love You, Willison’s explanation makes perfect sense. Shane documents many cases in which AI software, given a task, takes “shortcuts”. Because computers and software are literal (paperclip maximizers, these shortcuts are sometimes surprising to humans. Here, OpenAI removed the guardrails, locked the model in a sandbox, and told it to solve a bunch of benchmark problems. The model “cheated” – that is, instead of working directly on the problems, it found a vulnerability in the sandbox that let it access the public Internet, and attacked Hugging Face as a likely source of the problems’ solutions. If it were a new-model car kept in a locked parking lot that turned itself on, crashed through the barriers, and drove into a house across the street, it wouldn’t seem so mystical; we’d expect the company to revamp the car’s electrical system, strengthen the barriers, and pay for the damage.

Willison goes on to argue that a key issue is asymmetry of knowledge – that is, that the guardrails that protect us from “our” AI software don’t apply elsewhere, so blocks on Chinese AIs prevent us for finding the vulnerabilities in our own software and services that they can. At last, a sensible reason for caring if another country is “winning the AI race” (whatever that really means).

Illustrations: Children swimming in the summer, by Japanese artist Ando Hiroshige, 1797-1858 (via Smithsonian collection.

Also this week: The Plutopia podcast talks with Rob van Eijk on digital sovereignty, AI, and privacy in the EU.

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.