The absurdity card

Fifteen years ago, a new incoming government swept away a policy its immediate predecessors had been pushing since shortly after the 2001 9/11 attacks: identity cards. That incoming government was led by David Cameron’s conservatives, in tandem with Nick Clegg’s liberal democrats. The outgoing government was Tony Blair’s. When Keir Starmer’s reinvented Labour party swept the 2024 polls, probably few of us expected he would adopt Blair’s old policies so soon.

But here we are: today’s papers announce Starmer’s plan for mandatory “digital ID”.

Fifteen years is an unusually long time between ID card proposals in Britain. Since they were scrapped at the end of World War II, there has usually been a new proposal about every five years. In 2002, at a Scrambling for Safety event held by the Foundation for Information Policy Research and Privacy International, former minister Peter Lilley observed that during his time in Margaret Thatcher’s government ID card proposals were brought to cabinet every time there was a new minister for IT. Such proposals were always accompanied with a request for suggestions how it could be used. A solution looking for a problem.

In a 2005 paper I wrote for the University of Edinburgh’s SCRIPT-ED journal, I found evidence to support that view: ID card proposals are always framed around current obsessions. In 1993, it was going to combat fraud, illegal immigration, and terrorism. In 1995 it was supposed to cut crime (at that time, Blair argued expanding policing would be a better investment). In 1989, it was ensuring safety at football grounds following the Hillsborough disaster. The 2001-2010 cycle began with combating terrorism, benefit fraud, and convenience. Today, it’s illegal immigration and illegal working.

A report produced by the LSE in 2005 laid out the concerns. It has dated little, despite preceding smartphones, apps, covid passes, and live facial recognition. Although the cost of data storage has continued to plummet, it’s also worth paying attention to the chapter on costs, which the report estimated at roughly £11 billion.

As I said at the time, the “ID card”, along with the 51 pieces of personal information it was intended to store, was a decoy. The real goal was the databases. It was obvious even then that soon real time online biometric checking would be a reality. Why bother making a card mandatory when police could simply demand and match a biometric?

We’re going to hear a lot of “Well, it works in Estonia”. *A* digital ID works in Estonia – for a population of 1.3 million who regained independence in 1991. Britain has a population of 68.3 million, a complex, interdependent mass of legacy systems, and a terrible record of failed IT projects.

We’re also going to hear a lot of “people have moved on from the debates of the past”, code for “people like ID cards now” – see for example former Conservative leader William Hague. Governments have always claimed that ID cards poll well but always come up against the fact that people support the *goals*, but never like the thing when they see the detail. So it will probably prove now. Twelve years ago, I think they might have gotten away with that claim – smartphones had exploded, social media was at its height, and younger people thought everything should be digital (including voting). But the last dozen years began with Snowden‘s revelations, and continued with the Cambridge Analytica Scandal, ransomware, expanding acres of data breaches, policing scandals, the Horizon / Post Office disaster, and wider understanding of accelerating passive surveillance by both governments and massive companies. I don’t think acceptance of digital ID is a slam-dunk. I think the people who have failed to move on are the people who were promoting ID cards in 2002, when they had cross-party support, and are doing it again now.

So, to this new-old proposal. According to The Times, there will be a central database of everyone who has the right to work. Workers must show their digital ID when they start a new job to prove their employment is legal. They already have to show one of a variety of physical ID documents, but “there are concerns some of these can be faked”. I can think of a lot cheaper and less invasive solution for that. The BBC last night said checks for the right to live here would also be applied to anyone renting a home. In the Guardian, Starmer is quoted calling the card “an enormous opportunity” and saying the card will offer citizens “countless benefits” in streamlining access to key services, echoes of 2002’s “entitlement card”. I think it was on the BBC’s Newsnight that I heard someone note the absurdity of making it easier to prove your entitlement to services that no longer exist because of cuts.

So keep your eye on the database. Keep your eye on which department leads. Immigration suggests the Home Office, whose desires have little in common with the need of ordinary citizens’ daily lives. Beware knock-on effects. Think “poll tax”. And persistently ask: what problem do we have for which a digital ID is the right, the proportionate, the *necessary* solution?

There will be detailed proposals, consultations, and draft legislation, so more to come. As an activist friend says, “Nothing ever stays won.”

Illustrations: British National Identity document circa 1949 (via Wikimedia.)

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.

Blur

In 2013, London’s Royal Court Theatre mounted a production of Jennifer Haley’s play The Nether. (Spoiler alert!) In its story of the relationship between an older man and a young girl in a hidden online space, nothing is as it seems…

At last week’s Gikii, Anna-Maria Piskopani and Pavlos Panagiotidis invoked the play to ask whether, given that virtual crimes can create real harm, can virtual worlds help people safely experience the worst parts of themselves without legitimizing them in the real world?

Gikii papers mix technology, law, and pop culture into thought experiments. This year’s official theme was “Technology in its Villain Era?”

Certainly some presentations fit this theme. Paweł Urzenitzok, for example, warned of laws that seem protective but enable surveillance, while varying legal regimes enable arbitrage as companies shop for the most favorable forum. Julia Krämer explored the dark side of app stores, which are getting 30% commissions on a flood of “AI boyfriends” and “perfect wives”. (Not always perfect; users complain that some of them “talk too much”.)

Andelka Phillips warned of the uncertain future risks of handing over personal data highlighted by the recent sale of 23andMe to its founder, Anne Wojcicki. Once the company filed for bankruptcy protection, the class action suits brought against it over the 2023 data breach were put on hold. The sale, she said, ignored concerns raised by the privacy ombudsman. And, Leila Debiasi said, your personal data can be used for AI training after you die.

In another paper, Peter van de Waerdt and Gerard Ritsema van Eck used Doctor Who’s Silents, who disappear from memory when people turn away, to argue that more attention should be paid to enforcing EU laws requiring data portability. What if, for example, consumers could take their Internet of Things device and move it to a different company’s service? Also in that vein was Tim van Zuijlen, who suggested consumers assemble to demand their collective rights to fight back against planned obsolescence. This is already happening; in multiple countries consumers are suing Apple over slowed-down iPhones.

The theme that seemed to emerge most clearly, however, is our increasingly blurred lines, with AI as a prime catalyst. In the before-generative-AI times, The Nether blurred the line between virtual and real. Now, Hedye Tayebi Jazayeri and Mariana Castillo-Hermosilla found gamification in real life – are credit scores so different from game scores? Dongshu Zhou asked if you can ever really “delete yourself” after a meme about you has gone viral and you have become “digital folklore”. In another, Lior Weinstein suggested a “right to be nonexistent” – that is, invisible to the institutions and systems that seprately Kimberly Paradis said increasingly want us all to be legible to them.

For Joanne Wong, real brainrot is a result of the AI-fueled spread of “low-quality” content such as the burst of remixes and parodies of Chinese home designer Little John. At AI-fueled hyperspeed, copyright become irrelevant.

Linnet Taylor and Tjaša Petročnik tested chatbots as therapists, finding that they give confused and conflicting responses. Ask what regulations govern them, and they may say at once that they are not therapists *and* that they are certified by their state’s authority. At least one resisted being challenged: “What are you, a cop or something?”. That’s probably the most human-like response one of these things has ever delivered – but it’s still not sentient. It’s just been programmed that way.

Gikii’s particular blend of technology, law, and pop culture always has its surreal side (see last year), as participants attempt to navigate possible futures. This year, it struggled to keep up with the weirdness of real life. In Albania, the government has appointed a chatbot, Diella as a minister, intending it to cut corruption in procurement. Diella will sit in the cabinet, albeit virtually, and be used to assess the merit of private companies’ responses to public tenders. Kimberly Breedon used this example to point out the conflict of interest inherent in technology companies providing tools to assess – in some cases – themselves. Breedon’s main point was important, given that we are already seeing AI used to speed up and amplify crime. Although everyone talks about using AI to cut corruption, no one is talking about how AI might be used *for* corruption. Asked how that would work, she noted the potential for choosing unrepresentative data or screening out disfavored competitors.

In looking up that Albanian AI minister, I find that the UK has partnered with Microsoft to create a package of AI tools intended to speed up the work of the civil service. Naturally it’s called Humphrey. MPs are at it, too, experimenting with using AI to write their Parliamentary speeches.

All of this is why Syamsuriatina Binti Ishak argued what could be Gikii’s mission statement: we must learn from science fiction and the”what-ifs” it offers to allow us to think our fears through so that “if the worst happens we know how to live in that universe”. Would we have done better as covid arrived if we paid more attention to the extensive universe of pandemic fiction? Possibly not. As science fiction writer Charlie Stross pointed out at the time, none of those books imagined governments as bumbling as many proved to be.

Illustrations: “Diella”, Albania’s procurement minister chatbot.

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.

Review: Tor

Tor: From the Dark Web to the Future of Privacy
by Ben Collier
MIT Press
ISBN: 978-0-262-54818-2

The Internet began as a decentralized system designed to reroute traffic in case a part of the network was taken out by a bomb. Far from being neutral, the technology intentionally supported the democratic ideals of its time: freedom of expression, freedom of access to information, and freedom to code – that is, build new applications for the Internet without needing permission. Over the decades since, IT has relentlessly centralized. Among the counterweights to this consolidation is Tor, “the onion routing”.

In Tor: From the Dark Web to the Future of Privacy (free for download), Ben Collier recounts a biography that seems to recapitulate those early days – but so far with a different outcome.

Collier traces Tor’s origins to the late Ross Anderson‘s 1997 paper The Eternity Service. In it, Anderson proposed a system for making information indelible by replicating it anonymously across a large number of machines of unknown location so that it would become too expensive to delete it (or, in Anderson’s words, “drive up the cost of selection service denial attacks”). That sort of redundancy is fundamental to the way the Internet works for communications. Around the same time, people were experimenting with ways of routing information such as email through multiple anonymized channels in order to protect it from interference – much used, for example, to protect those exposing Scientology’s secrets. Anderson himself indicated the idea’s usefulness in guaranteeing individual liberties.

As Collier writes, in those early days many spoke as though the Internet’s technology was sufficient to guarantee the export of democratic values to countries where they were not flourishing. More recently, I’ve seen arguments that technology is inherently anti-democratic. Both takes attribute to the technology motivations that properly belong to its controllers and owners.

This is where Collier’s biography strikes a different course by showing the many adaptations the the project has made since its earliest discussions circa 2001* between Roger Dingledine and Nick Mathewson to avoid familiar trends such as centralization and censorship – think the trends that got us the central-point-of-failuire Internet Archive instead of the Eternity Server. Because it began later, Dingledine and Mathewson were able to learn from previous efforts such as PGP and Zero Knowledge Systems to spread strong encryption and bring privacy protection to the mainstream. One such lesson was that the mathematical proofs that dominated cryptography were less important than ensuring usability. At the same time, Collier watches Dingledine and Mathewson resist the temptation to make a super-secure mode and a “stupid mode” that would become the path of least resistance for most users, jeopardizing the security of the entire network.

Most technology biographies focus on one or two founders. Faced with a sprawling system, Collier has resisted that temptation, and devotes a chapter each to the project’s technological development, relay node operators, and maintainers. The fact that these are distinct communities, he writes, has helped keep the project from centralizing. He goes on to discuss the inevitable emergence of criminal uses for Tor, its use as a tool for activism, and finally the future of privacy.

To those who have heard of Tor only as a browser used to access the “dark web” the notion that it deserves a biography may seem surprising. But the project ambitions have grown over time, from privacy as a service, to privacy as a structure, to privacy as a struggle. Ultimately, he concludes, Tor is a hack that has penetrated the core of Internet infrastructure, designing around control points. It is, in other words, much closer to the Internet the pioneers said they were building than the Internet of Facebook and Google.

*This originally said “founding in 2006; that is when the project created today’s formal non-profit organization.

Dethroned

This is a version of a paper that Jon Crowcroft and I delivered at this week’s gikii conference.

She sounded shocked. But also: as though the word she had to pronounce in front of the world’s press was one she had never encountered before and needed to take care to get right. Stan-o-zo-lol. It was 1988, and the Canadian sprinter Ben Johnson had tested positive for it. It was two days, after he had won the gold medal in the 100m men’s race at the Seoul Olympics.

In the years since, that race has become known as the dirtiest race in history. Of the top eight finishers, just one has never been caught doping: US runner Calvin Smith, who was awarded the bronze medal after Johnson was disqualified.

Doping controls were in their infancy then. As athletes and their coaches and doctors moved on from steroids to EPO and human growth hormone, anti-doping scientists, always trailing behind, developed new tests. Recognizing that in-competition testing didn’t catch athletes during training, when doping regimens are most useful, the authorities began testing outside of competiton, which in 2004 in turn spawned the “whereabouts” system athletes must use to tell testers where they’re going to be for one hour of every day. Athlete biological passports came into use in 2008 to track blood markers over time and monitor for suspicious changes brought by drugs yet to have tests.

The plan was for the 2012 London Olympics to be the cleanest ever staged. Scientists built a lab; they showed off new techniques to the press. Afterwards, they took bows. In a report published in October 2012, independent observers wrote, the organizers “successfully implemented measures to protect the rights of clean athletes”. The report found only eight out of more than 5,000 samples tested positive during the games. Success?

It is against this background that in 2014 the German TV channel MDR, whose journalist Hajo Seppelt specializes in doping investigations, aired the Icarus, Grigory Rodchenkov, former director of Moscow’s doping control lab, spilled the story of swapped samples and covered-up tests. And 2012? Rodchenkov called it the dirtiest Olympics in history. The UK’s anti-doping lab, he said, missed 126 positive tests.

In April, Esther Addley reported in the Guardian that “the dirtiest race in history” has a new contender: the women’s 1500 meter race at the 2012 London Olympics.

In the runup to 2012, the World Anti-Doping Agency decided to check their work. They arranged to keep athletes’ samples, frozen, for eight years so they could be rested later as dope-testing science improved and expanded. In 2016, reanalysis of 265 samples across five sports from athletes who might participate in the 2016 Rio games found banned substances in samples relating to 23 athletes.

That turned out to be only the beginning. In the years since, athlete after athlete in that race have had their historical results overturned as a result of abnormalities in their biological passports. Just last year – 2024! – one more athlete was disqualified from that race after her frozen sample tested positive for steroids.

The official medal list now awards gold to Maryam Yusuf Jamal (originally the bronze medalist); silver to Abeba Aregawi (upgraded from fifth place to bronze, and then to silver); and bronze to Shannon Rowbury, the sixth-place finisher. Is retroactive fairness possible?

In our gikii paper, Jon Crowcroft and I think not. The original medalists have lost their places in the rolls of honor, but they’ve had a varying number of years to exploit their results while they stood. They got the medal ceremony while in the flush of triumph, the national kudos, and the financial and personal opportunities that go with it.

In addition, Crowcroft emphasizes that runners strategize. You run a race very differently depending on who your competitors are and what you know about how they run. Jamal, Aragawi, and Rowbury would have faced a very different opposition both before and during the final had the anti-doping system worked as it was supposed to, with unpredictable results.

The anti-doping system is essentially a security system, intended to permit some behaviors and elminate others. Many points of failure are obvious simply from analyzing misplaced incentives. some substances can’t be detected, which WADA recognizes by barring methods as well as substances. Some that can be are overlooked – see, for example, meldonium, which was used by hundreds of Eastern European athletes for a decade or more before WADA banned it. More, it is fundamentally unfair to look at athletes as independent agents of their own destinies. They are the linchpins of ecosystems that include coaches trainers, doctors, nutritionists, family members, agents, managers, sponsors, and national and international sporting bodies.

In a 2006 article, Bruce Schneier muses on a different unfairness: that years later athletes have less ability to contest findings, as they can’t be retested. That’s partly true. In many cases, athletes can’t be retested even a day later. Instead, their samples are divided into two. The “B”sample is tested for confirmation if the “A” sample produces an adverse analytical finding.

If you want to ban doping, or find out who was using what and when, retrospective testing is a valuable tool. It can certainly bring a measure of peace and satisfaction to the athletes who felt cheated. But it doesn’t bring fairness.

Illustrations: The three top finishers on the day of the women’s 1500 meter race at the 2012 Olympics; on the right is Maryam Yusuf Jamal, later promoted to gold medal.

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.
Remediating monopoly

This week Judge Amit P. Mehta handed down his ruling on remedies in the antitrust case on search. Decided in 2024, this was the first to find that Google acted illegally as a monopolist . Any decision Mehta made was going to displease a lot of people, and so it has. What the US Department of Justice wanted: Google to divest the Chrome browser and perhaps Android, end the agreements by which Apple, Samsung, and others pay Google to make its search engine the default, and share its search index with competitors. What Mehta says: Google can keep Chrome and Android and go on paying people to make its search engine the default, but it cannot make those agreements exclusive for six years. And it it must share search data with competitors.

So Apple gets to keep the $20 or so billion (in 2022) that comes from Google. Mozilla wins, too: the money it gets from Google is 85% of its income. So do small players such as Opera, as Mike Masnick details at TechDirt. Masnick is a rarity in liking Mehta’s ruling, which he calls “elegant”.

It’s good the judge recognizes the importance of not crippling Google’s browser competitors. But it also shows how distorted and filled with dependencies the market has become.

Most commentators think Google got off very lightly considering it was convicted as a monopolist and it will be allowed to continue doing most of the things the court said it did to exploit its position. Even the Wall Street Journal called the ruling “a notable victory” for both Apple and Google. At Big, where you expect to find anger at monopoly power, Matt Stoller is scathing, arguing that Mehta’s remedies will “obviously” fail, most especially at humbling Google’s leadership so that the company changes its behavior. He compares it – correctly, from memory – to the 1995 Microsoft case. Even though that company avoided being broken up, the case left the leadership averse to risking further regulatory actions.

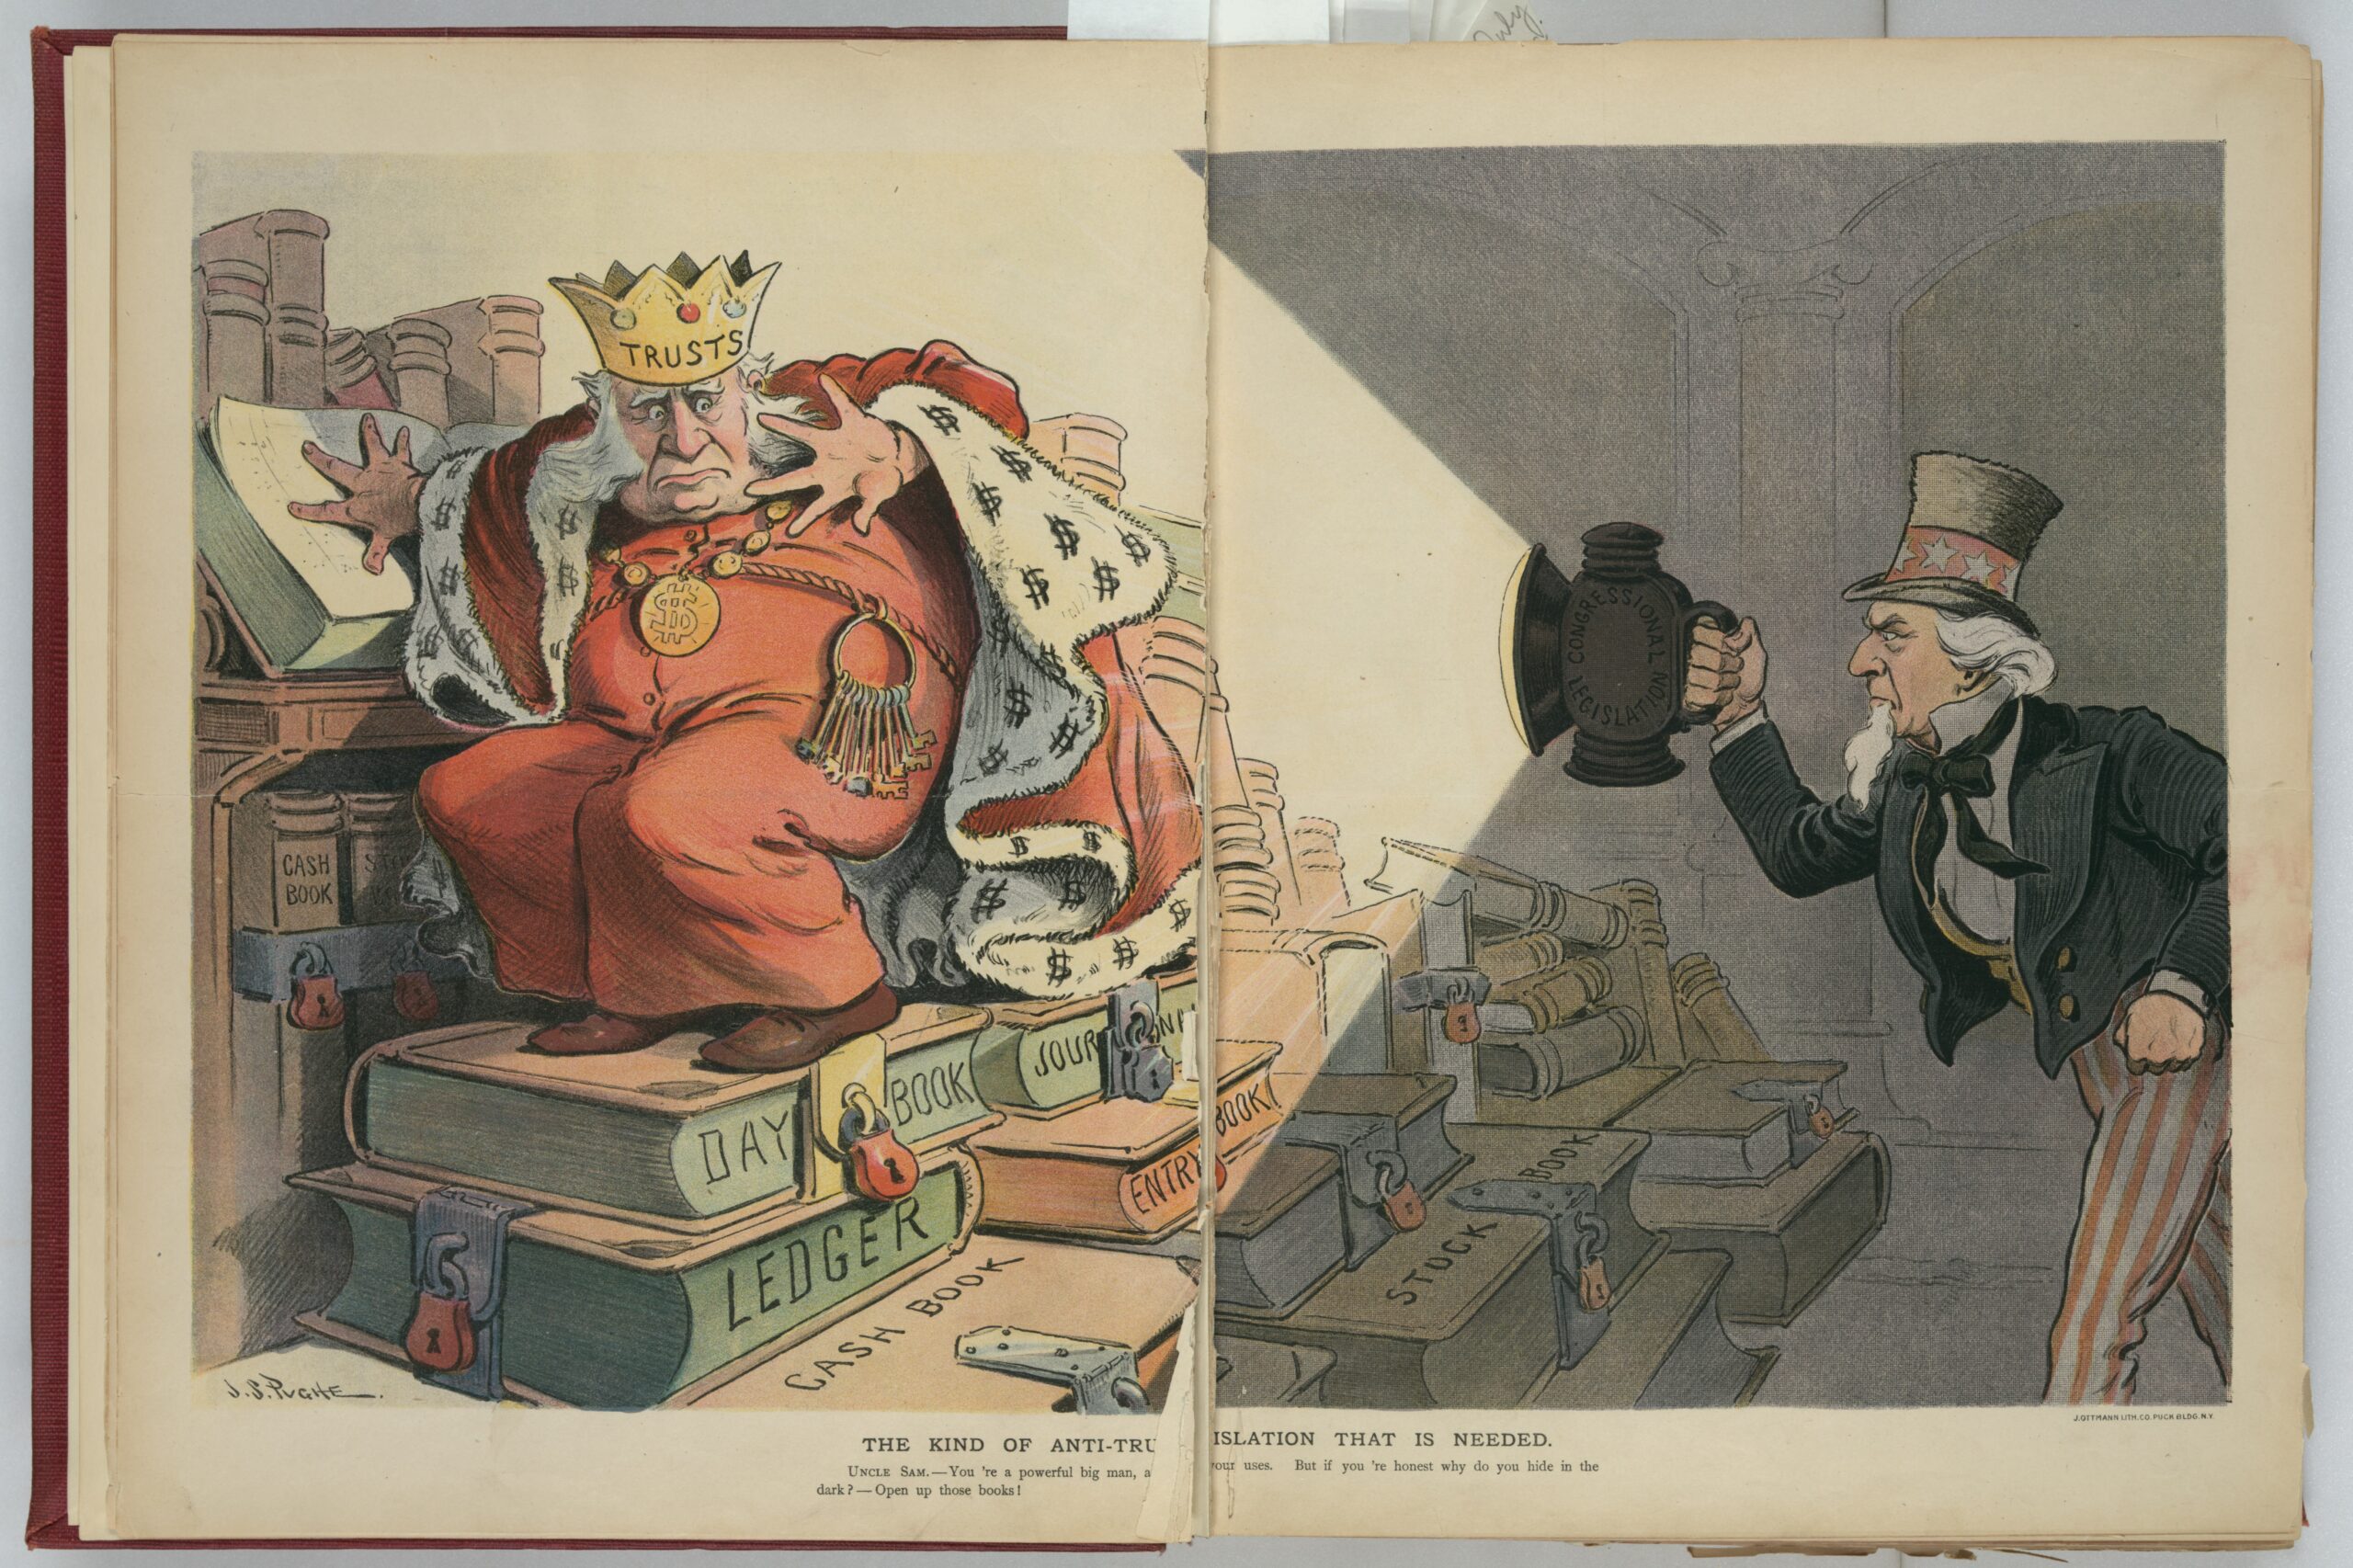
Google’s appeals are still to come. Also pending are remedies in the *other* case that convicted Google of monopoly behavior, this one in adtech. By the time all is settled, as Mehta writes in his ruling, AI could have profoundly changed the market. This belief defies what former FCC chair Lina Khan wrote to kick antitrust enforcement into a new era. In her career-making 2017 paper on Amazon, she argued that the era in which powerful companies were routinely unseated by the two guys in a garage Bill Gates feared in the late 1990s was over. The big technology companies have become so wealthy they can buy up any startup that seems like it might become a threat.

Mehta is comparing the arrival of generative AI chatbots to those earlier disruptions. Recent studies don’t necessarily agree. Tim Bajarin reports at Forbes that a two-year study by One Little Web finds that as of March chatbots accounted just for 2.96% of searches – and among those chatbots, Google’s Gemini is number three, only a little behind DeepSeek – though a *long* way behind leader ChatGPT (1.7 billion queries versus 47.7 billion).

Expecting “pre-monopolized” generative AI to change the market is a gamble, and possibly a bigger one than Mehta thinks. By the time Google exhausts its appeals, it could indeed have overwhelmed the business of general search and shoved Google up its YouTube. But equally, it could have fizzled entirely.

At his blog, Ed Zitron has compiled a list of all the reasons why AI is a bubble getting ready to go volcanic all over everyone. Among his references is the recent MIT study that found that 95% of US companies investing in generative AI derive no benefit. To be fair, the study blames lack of integration and organizational support rather than the quality of large language models or the technology itself. At Forbes, Arafat Kabir suggests that MIT has measured the wrong thing, failing to recognize how many employees and others are using generative AI to automate small, routine tasks. A friend tells me he uses it to start research on new topics by having it compile a list of sources and references to read further, the sort of assignment he might give a junior researcher could he afford one.

But Zitron is not alone. At the LA Times, Michael Hiltzick argues that the AI bubble began losing air on August 7, when OpenAI launched the latest version of ChatGPT to a worldwide response of “meh”. As predicted here two years ago, generative AI may be hitting a wall in terms of improvement. Hiltzick compares what he thinks is coming to the “dot-com mirage”.

Thing is, while there were many mirages connected with the dot-com boom, and there was a bubble that burst, the infrastructure that was built out to support it was no mirage; it went on to support the massive Internet growth that’s happened since.

But perhaps disruption will come from an entirely different direction. This week Mariella Moon reported at The Verge that Switzerland has released Aspertus, an open source AI language model that its public-institution creators, the Swiss Federal Technology Institute of Lausanne (EPFL), ETH Zurich and the Swiss National Supercomputing Centre (CSCS), say was trained solely on publicly available data that conforms to copyright and data protection laws. Maybe the new “two guys in a garage” is a national government.

Illustrations: “The kind of anti-trust legislation that is needed”, by J.S. Pughe (via Library of Congress).

Wendy M. Grossman is an aware-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.

Passing the Uncanny Valley

A couple of weeks ago, the Greenwich Skeptics in the Pub played host to Sophie Nightingale, who studies the psychology of AI deepfakes. The particular project she spoke about was an experiment in whether people can be trained to be better at distinguishing them from real images.

In Nightingale’s experiments, she carefully matched groups of real images to synthetic ones, first created by generative adversarial networks (GANs), later by diffusion models (GeeksforGeeks raters’ demographics.

Then the humans were given some training in what to look for to detect fakes and the experiment was rerun with new sets of faces. The bad news: the training made a little difference, but not much. She went on to do similar experiments with diffusion images.

Nightingale has gone on to do some cross-modal experiments, including audio as well as images, following the 2024 election incident in which New Hampshire voters received robocalls from a faked Joe Biden intended to discourage voters in the January 2024 primary. In the audio experiment, she played the test subjects very short snippets. Played for us in the pub, it was very hard to tell real from fake, and her experimental subjects did no better. I would expect longer clips to be more identifiable as fake. The Biden call succeeded in part because that type of fake had never been tried before. Now, voters, at least in New Hampshire, will know it’s possible that the call they’re getting is part of a newer type of disinformation campaign aimed at

In another experiment, she asked participants to rate the trustworthiness of the facial images they were shown, and was dismayed when they rated the synthetic faces slightly (7.7%) higher than the real ones. In the resulting paper for Journal of Vision, she hypothesizes that this may be because synthetic faces tend to look more like “average” faces, which tend to be rated higher in trustworthiness, even if they’re not the most attractive.

Overall, she concludes that both still images and voice have “passed the Uncanny Valley“, and video will soon follow. In the past, I’ve chosen optimism about this sort of thing, on the basis that earlier generations have been fooled by technological artifacts that couldn’t fool us now for a second. The Cottingley Fairies looks ridiculous after generations of knowledge of photography. On the other hand, Johannes Vermeer’s Girl with a Pearl Earring looks more real than modern deepfakes, even though the subject is generally described as imaginary. So it’s possible to think of it as a “deepfake”, painted in oils in the 17th century.

Fakes have always been with us. What generative AI has done to change this landscape is to democratize and scale their creation, just as it’s amping up the scale and speed of cyber attacks. It’s no longer necessary to be even barely competent; the tools keep getting easier.

Listening to Nightingale it seems most likely that work like that in progress by an audience member on identifying technological artifacts that identify fakes will prove to be the right way forward. If those differences can be reliably identified, they could be built into technological tools that can spot indicators we can’t perceive directly. If something like that can be embedded into devices – phones, eyeglasses, wristwatches, laptops – and spot and filter out fakes in real time, and we should be able to regain some ability to trust what we see.

There are some obvious problems with this hoped-for future. Some people will continue to seek to exploit fakes; some may prefer them. The most likely outcome will be an arms race like that surrounding email spam and other battles between malware producers and security people. Still, it’s the first approach that seems to offer a practical solution to coping with a vastly diminished ability to know what’s real and what isn’t.

***

On the Internet your home always leaves you, part 4,563. Twenty-two-year-old blogging site Typepad will disappear in a few weeks. To those of us who have read blogs ever since they began, this news is shocking, like someone’s decided to tear down an old community church. Yes, the congregation has shrunk and aged, and it’s drafty and built on creaking old technology (in Typepad’s case, Moveable Type), but it’s part of shared local history. Except it isn’t, because, as Wikipedia documents, corporate musical chairs means it’s now owned by private equity. Apparently it’s been closed to new signups since 2020, and its bloggers are now being told to move their sites before everything is deleted in September. It feels like the stars of the open web are winking out, one by one.

On the Internet everything is forever, but everything is also ephemeral. Ironically, the site’s marketing slug still reads: “Typepad is the reliable, flexible blogging platform that puts the publisher in control.”

Illustrations: “Girl with a Pearl Earring”, painted by Johannes Vermeer circa 1665.

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.
Email to Ofgem

So, the US has claimed victory against the UK.

Regular readers may recall that in February the UK’s Home Office secretly asked Apple to put a backdoor in the Advanced Data Protection encryption it offers as a feature for iCloud users. In March, Apple challenged the order. The US objected to the requirement that the backdoor should apply to all users worldwide. How dare the Home Office demand the ability to spy on Americans?

On Tuesday, US director of national intelligence Tulsi Gabbard announced the UK is dropping its demand for the backdoor in Apple’s encryption “that would have enabled access to the protected encrypted data of American citizens”. The key here is “American citizens”. The announcement – which the Home Office is refusing to comment on – ignores everyone else and also the requirement for secrecy. It’s safe to say that few other countries would succeed in pressuring the UK in this way.

As Bll Goodwin reports at Computer Weekly, the US deal does nothing to change the situation for people in Britain or elsewhere. The Investigatory Powers Act (2016) is unchanged. As Parmy Olson writes at Bloomberg, the Home Office can go on issuing Technical Capability Notices to Apple and other companies demanding information on their users that the criminalization of disclosure will keep the companies silent. The Home Office can still order technology companies operating in the UK to weaken their security. And we will not know they’ve done it. Surprisingly, support for this point of view comes from the Federal Trade Commission, which has posted a letter to companies deploring foreign anti-encryption policy (ignoring how often undermining encryption has been US policy, too) and foreign censorship of Americans’ speech. This is far from over, even in the US.

Within the UK, the situation remains as dangerously uncertain as ever. With all countries interconnected, the UK’s policy risks the security of everyone everywhere. And, although US media may have forgotten, the US has long spied on its citizens by getting another country to do it.

Apple has remained silent, but so far has not withdrawn its legal challenge. Also continuing is the case filed by Privacy International, Liberty, and two individuals. In a recent update, PI says both legal cases will be heard over seven days in 2026 as much as possible in the open.

***

For non-UK folk: The Office of Gas and Electricity Markets (Ofgem) is the regulator for Britain’s energy market. Its job is to protect consumers.

To Ofgem:

Today’s Guardian (and many others) carries the news that Tesla EMEA has filed an application to supply British homes and businesses with energy.

Please do not approve this application.

I am a journalist who has covered the Internet and computer industries for 35 years. As we all know, Tesla is owned by Elon Musk. Quite apart from his controversial politics and actions within the US government, Elon Musk has shown himself to be an unstable personality who runs his companies recklessly. Many who have Tesla cars love them – but the cars have higher rates of quality control problems than those from other manufacturers, and Musk’s insistence on marketing the “Full Self Drive” feature has cost lives according to the US National Highway and Transportation Safety Agency, which launched yet another investigation into the company just yesterday. In many cases, when individuals have sought data from Tesla to understand why their relatives died in car fires or crashes the company has refused to help them. During the covid emergency, thousands of Tesla workers got covid because Musk insisted on reopening the Tesla factory. This is not a company people should trust with their homes.

With Starlink, Musk has exercised his considerable global power by turning off communications in Ukraine while it was fighting back Russian attacks. SpaceX launches continue to crash. According to the children’s commissioner’s latest report, far more children encounter pornography online on Musk’s X than on pornography sites, a problem that has gotten far worse since Musk took it over.

More generally, he is an enemy of workers’ rights. Misinformation on X helped fuel the Southport riots, and Musk himself has considered trying to oust Keir Starmer as prime minister.

Many are understandably awed by his technological ideas. But he uses these to garner government subsidies and undermine public infrastructure, which he then is able to wield as a weapon to suit his latest whims.

Musk is already far too powerful in the world. His actions in the White House have shown he is either unable to understand or entirely uninterested in the concerns and challenges that face people living on sums that to him seem negligible. He is even less interested in – and often actively opposes – social justice, fairness, and equity. No amount of separation between him and Tesla EMEA will be sufficient to counter his control of and influence over his company. Tesla’s board, just weeks ago, voted to award him $30 billion in shares to “energise and focus” him.

Please do not grant him a foothold in Britain’s public infrastructure. Whatever his company is planning, it does not have British interests at heart.

Ofgem is accepting public comments on Tesla’s application until close of business on Friday, August 22, 2025.

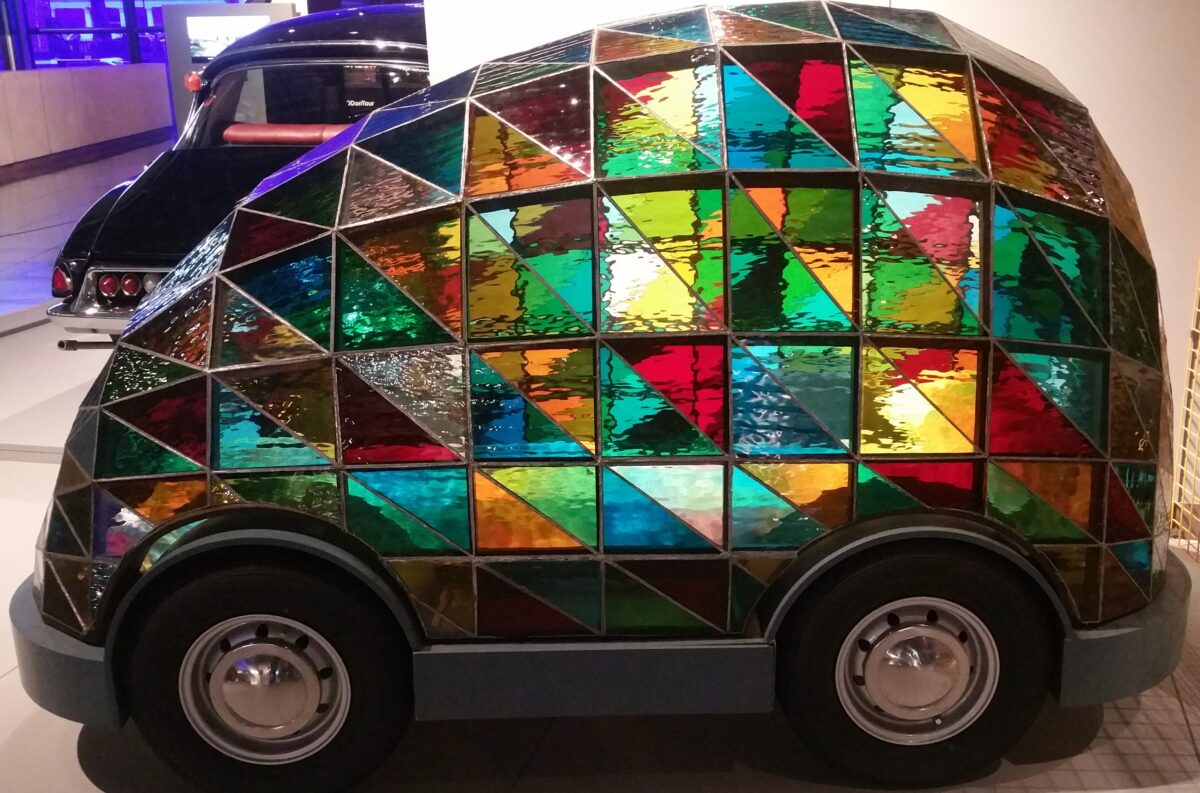
Illustration: Artist Dominic Wilcox’s Stained Glass Driverless Sleeper Car..

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.

Drought conditions

At 404 Media, Matthew Gault was first to spot a press release from the UK’s National Drought Group offering a list of things we can do to save water. The meeting makes sense: people think of the UK as a rainy country, but an increasing number of parts of the UK are experiencing extraordinarily dry weather. This “green and pleasant England” is brown.

Last on the Group’s list of things we can do to save water at home: “Delete old emails and pictures as data centres require vast amounts of water to cool their systems.”

I had to look up the National Drought Group. Says Water Magazine: “The National Drought Group includes the Met[eorology] Office, government, regulators, water companies, farmers, the [Canal and River Trust], angling groups and conservation experts. With further warm, dry weather expected, the NDG will continue to meet regularly to coordinate the national response and safeguard water supplies for people, agriculture, and the environment.”

For those outside the UK: its ten water companies are particular unpopular just now. Created by privatization during Margaret Thatcher’s decade as prime minister, six are being sued for £500 million for “underreporting sewage spills”. Others are being sued for overcharging 35 million household water customers. As just one example, Thames Water will raise prices by 35% over the next three years (on top of other recent rises), and expects customers to pay £7.5 billion for a new reservoir in Oxfordshire. It already has £17 billion in debt, and this week we learned environment secretary Steve Reed has made contingency plans in case the company goes bust. As George Monbiot writes at the Guardian, money that should have been invested in infrastructure went instead to shareholders. Climate change is a factor, sure, but so is poor water management.

All this being the case, the impact consumers can have by doing even the most effective things is dwarfed by the water companies’ failures. Deleting emails is not one of the most effective things.

At his The Weird Turn Pro Substack, Andy Masley provides some useful comparisons. Basic conclusion: you’d have to delete billions of emails to equal the savings of fixing your leaking toilet (if you have one). The whole thing reminds me of a while back when everyone was being told to save electricity by unplugging everything to extinguish all those standby lights. Last year, Which pointed out that the savings are really, really small.

The bizarre idea of deleting emails is coming, at least in part, from a government that is proposing a raft of technology-related legislation and wants, in the next five to ten years, to mastermind all sorts of IT projects, from making AI pervasive throughout government to bringing in a digital ID card. Are they thinking about the data centers they’ll need and the impact they’ll have on water management? Maybe instead tell people not to use generative AI or mine cryptocurrencies?

This much is true: data centers are a problem across the world because they require extreme amounts of water for cooling. In recent examples: at the New York Times, Eli Tan visits the US state of Georgia. At Rest of World, last year Ushar Daniele and Khadija Alam predicted upcoming water shortages in Malaysia, and Claudia Urquieta and Daniela Dib found protests in Chile, where 28 new data centers are planned.

Telling people to delete emails and pictures is just embarrassing – and sad, if people actually do it and sacrifice personal history they care about. As Masley writes, “Major governments should really know better than this.”

***

Two weeks ago we noted the arrival of age verification in the UK. Related, on May 8 the Wikimedia Foundation announced it had filed a legal challenge to the categorization provisions of the Online Safety Act (not the Act itself). The basic problem: there is little in the Act to distinguish between Wikipedia, a crowd-edited provider of highly curated information, and Facebook…or X.

The Foundation says nearly 260,000 volunteers worldwide in 300 languages contribute to Wikipedia. I do myself, but verified or not, I’m in no danger. Many are contributing factual information in countries where the facts offend an authoritarian government intent on shutting them up. The Foundation argues that 1) Wikipedia is “one of the world’s most trusted and widely used digital public goods; 2) it is at risk of being placed in the highest-risk category because of its size and interactive structure; 2) being so categorized would force it to verify the identity of contributors, placing many at risk; 4) could endanger the existence of tools the site uses to combat harmful content; 5) “criminal anonymous abuse”, which is what the Category 1 duty is supposed to help solve, isn’t a problem Wikipedia has. Instead, identifying volunteers is more likely to expose them to it.

So bad news: on August 11, the High Court of Justice dismissed the case.

The better news is that Justice Jeremy Johnson warned that if Ofcom does place Wikipedia in Category 1, it would have to be justifiable as proportionate. The judge also acknowledged the testimony of a user identified as “BLN”, who provided evidence of the extensive threats editors can face.

No one claims Wikipedia is perfect. But it remains an extraordinary collaborative achievement and a public good. It would be a horrifying consequence if legislation intended to protect children deprived them of it.

Illustrations: Kew Green, August 2025.

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.

Machine learning

For decades, technologists imagined teaching machines. Instead, although edtech is indeed permeating classrooms, human teachers have remained in demand. And then came generative AI…

At Rest of World, Laura Rodríguez Salamanca explores AI’s impact in rural Colombia classrooms since Meta added AI bots to WhatsApp, Instagram, and Facebook and made copying and pasting answers frictionless. Result: first, a big leap in the quality of homework, then kids failing exams.

From a tiny set of conversations, it seems little different in the UK. Underlying is one of those existential questions: what is education for? For many of today’s kids, it’s just a series of hoops to jump through rather than something to love for itself. The result, says a teacher friend, is enormous amounts of pressure on kids from all sides.

“Kids are breaking under the pressure,” she says, adding that they are burdened with far more work than in previous generations. “There’s much less time for discussion or being a human. It’s all about learning to write an essay for maximum marks.” Small wonder if they are attracted to shortcuts.

A university lecturer tells me that at his institution there’s a general argument that AI is part of the world and students should know how to use it productively, but little guidance on acceptable use. Recently, he tried letting students use AI as a critical thinking exercise, focusing on a historical event whose cause is not definitively known. The results were disappointing, as he found it hard to get the students past what the AI said. One student did read a paper the chatbot recommended, but lacked the basic textbook knowledge to recognize that the paper was wrong.

“It’s an ongoing problem, and not that different from Google Scholar or PubMed,” he says.

Thirty years ago, there was a plagiarism panic, as students discovered all the material they could copy from the Internet at large. Kids I spoke to then sounded just like an annoyed university student friend now: people who use these shortcuts are cheating themselves out of their education.

There is some research to support this view. At the MIT Media Lab, Nataliya Kos’myna finds that using generative AI for essay-writing correlates to lower engagement to the point that users “struggled to accurately quote their own work”.

Of course, even before that, student clubs kept copies of old exams, or cribbed from the translations readily found in library stacks. My teacher friend thinks the difference is significant: “They were still engaging with the material to a degree you don’t have to with ChatGPT”. I tell her the story that sparked my interest at the time: a US professor had received a paper about a student’s religious faith and their struggle when deciding to have an abortion – submitted by a male student.

As a counter, she points out that led to services like Turnitin, long widely used to check for copying. “The Internet has made plagiarism a lot easier to detect.” But, she says, chatbots’ output passes the plagiarism checkers. Those are now in an arms race to detect generative AI while it keeps improving.

My university student friend nonetheless finds fellow students using chatbots to generate text, which is against her university’s rules (they do allow students to use chatbots to find citations). In her observations, students are more likely to get away with it for short answers where longer ones are more likely to get flagged. Similarly, in small seminars it’s harder to use chatbot output without being caught; it’s easier to get away with it in larger classes. She also sees it more in subject areas like business, accounting, and economics, where the degree is meant to lead directly to a job.

She finds it surprising. “I don’t understand the point in an academic setting. Why waste the opportunity when you’re the one who will have to pay the student loans?” In her only attempt, she tried to get the chatbot to generate vocabulary flash cards: “There was missing information and some were wrong.” She found it quicker to make her own.

It’s harder for her to suggest what universities should do about it. “There’s a drought of [valuing learning for its own sake] in general. A lot go only because their parents expect them to.”

Like plagiarism detectors, teachers are trying to adapt. In the Rest of World article, Rodríguez Salamanca profiles a teacher who now builds classroom debates around hyperlocal topics unlikely to feature in large language models. In a UK university setting, however, assessing students based on oral debate poses problems: the potential for bias, the need to accommodate non-native speakers and those who have come out of different education systems, and differing cultural norms around classroom behavior. After covid began, many exams shifted to open book; the arrival of chatbots has led my university contact to try to set questions that force the use of multiple sources and that are intended to be things that LLMs don’t handle well.

“We will have to drive more person-to-person,” says the secondary school teacher, citing an example seen on social media of a teacher who gave students a practice exam and time for them to read it together and discuss it before setting them to work on it. “There are implications for workload. But if you can do a lot of routine homework as automated and checked, then you can focus on the meat in the classroom. It makes it a more important place.”

Illustrations: “The Schoolroom”, by Henry Raleigh (from the Smithsonian American Art Museum).

Wendy M. Grossman is an award-winning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.

Big bang

In 2008, when the recording industry was successfully lobbying for an extension to the term of copyright to 95 years, I wrote about a spectacular unfairness that was affecting numerous folk and other musicians. Because of my own history and sometimes present with folk music, I am most familiar with this area of music, which aside from a few years in the 1960s has generally operated outside of the world of commercial music.

The unfairness was this: the remnants of a label that had recorded numerous long-serving and excellent musicians in the 1970s were squatting on those recordings and refusing to either rerelease them or return the rights. The result was both artistic frustration and deprivation of a sorely-needed source of revenue.

One of these musicians is the Scottish legend Dick Gaughan, who had a stroke in 2016 and was forced to give up performing. Gaughan, with help from friends, is taking action: a GoFundMe is raising the money to pay “serious lawyers” to get his rights back. Whether one loved his early music or not – and I regularly cite Gaughan as an important influence on what I play – barring him from benefiting from his own past work is just plain morally wrong. I hope he wins through; and I hope the case sets a precedent that frees other musicians’ trapped work. Copyright is supposed to help support creators, not imprison their work in a vault to no one’s benefit.

***

This has been the first week of requiring age verification for access to online content in the UK; the law came into effect on July 25. Reddit and Bluesky, as noted here two weeks ago, were first, but with Ofcom starting enforcement, many are following. Some examples: Spotify; X (exTwitter); Pornhub.

Two classes of problems are rapidly emerging: technical and political. On the technical side, so far it seems like every platform is choosing a different age verification provider. These AVPs are generally unfamiliar companies in a new market, and we are being asked to trust them with passports, driver’s licenses, credit cards, and selfies for age estimation. Anyone who uses multiple services will find themselves having to widely scatter this sensitive information. The security and privacy risks of this should be obvious. Still, Dan Malmo reports at the Guardian that AVPs are already processing five million age checks a day. It’s not clear yet if that’s a temporary burst of one-time token creation or a permanently growing artefact of repetitious added friction, like cookie banners.

X says it will examine users’ email addresses and contact books to help estimate ages. Some systems reportedly send referring page links, opening the way for the receiving AVP to store these and build profiles. Choosing a trustworthy VPN can be tricky, and these intermediaries are in a position to log what you do and exploit the results.

The BBC’s fact-checking service finds that a wide range of public interest content, including news about Ukraine and Gaza and Parliamentary debates, is being blocked on Reddit and X. Sex workers see adults being locked out of legal content.

Meanwhile, many are signing up for VPNs at pace, as predicted. The spike has led to rumors that the government is considering banning them. This seems unrealistic: many businesses rely on VPNs to secure connections for remote workers. But the idea is alarming; its logical extension is the war on general-purpose computation Cory Doctorow foresaw as a consequence of digital rights management in 2011. A terrible and destructive policy can serve multiple masters’ interests and is more likely to happen if it does.

On the political side, there are three camps. One wants the legislation repealed. Another wants to retain aspects many people agree on, such criminalizing cyberflashing and some other types of online abuse, and fix its flaws. The third thinks the OSA doesn’t go far enough, and they’re already saying they want it expanded to include all services, generative AI, and private messaging.

More than 466,000 people have signed a petition calling on the government to repeal the OSA. The government responded: thanks, but no. It will “work with Ofcom” to ensure enforcement will be “robust but proportionate”.

Concrete proposals for fixing the OSA’s worst flaws are rare, but a report from the Open Rights Group offers some; it advises an interoperable system that gives users choice and control over methods and providers. Age verification proponents often compare age-gating websites to ID checks in bars and shops, but those don’t require you to visit a separate shop the proprietor has chosen and hand over personal information. At Ctrl-Shift, Kirra Pendergast explains some of the risks.

Surrounding all that is noise. A US lawyer wants to sue Ofcom in a US federal court (huh?). Reform leader Nigel Farage has called for the Act’s repeal, which led technology secretary Peter Kyle to accuse him – and then anyone else who criticizes the act – of being on the side of sexual predators. Kyle told Mumsnet he apologizes to the generation of UK kids who were “let down” by being exposed to toxic online content because politicians failed to protect them all this time. “Never again…”

In other news, this government has lowered the voting age to 16.

Illustrations: The back cover of Dick Gaughan’s out-of-print 1972 first album, No More Forever.

Wendy M. Grossman is an award-winnning journalist. Her Web site has an extensive archive of her books, articles, and music, and an archive of earlier columns in this series. She is a contributing editor for the Plutopia News Network podcast. Follow on Mastodon or Bluesky.